<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="http://www.stephen-cresswell.com/feed.xml" rel="self" type="application/atom+xml" /><link href="http://www.stephen-cresswell.com/" rel="alternate" type="text/html" /><updated>2026-08-29T15:47:14+00:00</updated><id>http://www.stephen-cresswell.com/feed.xml</id><title type="html">Signal Over Noise</title><author><name>Stephen Cresswell</name></author><entry><title type="html">Writing Better BDD with Yadda 3</title><link href="http://www.stephen-cresswell.com/2026/08/29/writing-better-bdd-with-yadda-3.html" rel="alternate" type="text/html" title="Writing Better BDD with Yadda 3" /><published>2026-08-29T00:00:00+00:00</published><updated>2026-08-29T00:00:00+00:00</updated><id>http://www.stephen-cresswell.com/2026/08/29/writing-better-bdd-with-yadda-3</id><content type="html" xml:base="http://www.stephen-cresswell.com/2026/08/29/writing-better-bdd-with-yadda-3.html"><![CDATA[<h2 id="introduction">Introduction</h2>

<p>With the release of Yadda 3, I’ve been revisiting not just the library itself, but how I think it should be used.</p>

<p>I’ve been working on Yadda for a long time, and over that time I’ve developed some fairly strong opinions about what makes a good executable specification. Most of them come back to one idea: the feature should optimise for communicating behaviour, not for making the test automation convenient. If the natural way to describe something is difficult to automate, the implementation should absorb that complexity rather than pushing it back into the feature.</p>

<p>This is one of the reasons Yadda is deliberately less prescriptive than traditional Gherkin. Given, When and Then are useful, but they aren’t mandatory. Step patterns can use dictionaries and converters to accommodate natural language, libraries can provide different implementations of similar steps, and features have several ways of removing repetition without sacrificing meaning.</p>

<p>There is another reason this matters more now than it did when Yadda was first written. Executable specifications are no longer consumed only by the people who wrote them and the test runner that executes them. Coding agents can use them too. A concise specification written in the language of the business gives an agent useful context about intended behaviour, including the edge cases and alternative paths that are easily lost when the only specification is the implementation itself.</p>

<p>That doesn’t require writing features for agents. Quite the opposite: the qualities that make a specification useful to a person, clear language, concrete examples, meaningful edge cases and minimal implementation noise, also make it useful context for an agent.</p>

<p>The guidelines below are the practices I’ve settled on for making use of Yadda’s flexibility. I’ve split them into two parts: first, how to write features and scenarios; then, how to implement the steps behind them. There is some deliberate overlap because the two influence each other. Good implementation should make better feature language possible, rather than constrain it.</p>

<h2 id="writing-features-and-scenarios">Writing Features and Scenarios</h2>

<h3 id="rule-1-simplicity-above-all">Rule 1: Simplicity above all</h3>

<p>The most important principle is simplicity, in the sense described by John Maeda in <a href="https://lawsofsimplicity.com">The Laws of Simplicity</a>:</p>

<blockquote>
  <p>“Simplicity is about subtracting the obvious, and adding the meaningful.”</p>
</blockquote>

<p>Simplicity does not mean making scenarios as short as possible. It means thoughtfully removing noise so that the important behaviour stands out. Remove repetition, unnecessary setup, implementation detail and obvious statements where they do not contribute to understanding. Conversely, do not remove information merely to make a scenario shorter. If something matters to understanding the behaviour, make it visible.</p>

<p>The rest of these guidelines largely follow from this principle.</p>

<h3 id="rule-2-speak-the-language-of-the-business">Rule 2: Speak the language of the business</h3>

<p>Features, scenarios and steps should use the natural language of the business domain. Avoid technical terminology and implementation details unless they are themselves meaningful business concepts. For example:</p>

<pre><code class="language-feature">Then they are told that the wine is unavailable
</code></pre>

<p>is preferable to:</p>

<pre><code class="language-feature">Then the API responds with a 404
</code></pre>

<p>when the behaviour being specified is whether a customer can order a particular wine.</p>

<p>The same principle applies to outcomes and assertions. Describe what happened in business terms rather than exposing HTTP responses, database columns, internal objects or other implementation details. Technical language is entirely appropriate when the technical behaviour itself is what you are specifying.</p>

<h3 id="rule-3-imagine-the-business-without-the-software">Rule 3: Imagine the business without the software</h3>

<p>A useful way to find natural business language is to imagine that the software does not exist. Ask how the same transaction would happen between people dealing directly with one another and with physical things. For example, imagine a customer in a restaurant:</p>

<pre><code class="language-feature">When the customer requests the wine list
And asks for the Sancerre "Les Baronnes" 2023
</code></pre>

<p>Both steps remain perfectly natural if the customer is speaking to a waiter rather than interacting with software. By contrast:</p>

<pre><code class="language-feature">When the client fetches the wine list
And sends a request for wine 2847
</code></pre>

<p>describes the software implementation.</p>

<p>A word does not become technical merely because software also uses it. <code class="language-plaintext highlighter-rouge">Request</code>, for example, works perfectly well here because requesting a wine list is a natural business interaction. The test is whether the language still makes sense when the computers are removed.</p>

<h3 id="rule-4-make-the-automation-fit-the-language">Rule 4: Make the automation fit the language</h3>

<p>Never make the business language awkward merely because it makes the automation easier to implement. Yadda provides mechanisms specifically intended to let the implementation accommodate natural language, so use them. Steps should be grammatically correct, and if natural English requires several variations of a sentence, support those variations rather than requiring unnatural grammar. Similarly, do not invent strange phrasing simply because it makes a regular expression easier to write or allows an existing step definition to be reused.</p>

<p>The feature is the specification. Implementation complexity belongs below it. See <a href="#rule-4-prefer-dictionaries-to-regular-expressions">Rule 4: Prefer dictionaries to regular expressions</a> and <a href="#rule-7-support-natural-grammar">Rule 7: Support natural grammar</a> for implementation techniques that help preserve natural feature language.</p>

<h3 id="rule-5-make-scenarios-interesting">Rule 5: Make scenarios interesting</h3>

<p>The main happy path matters, but it is often the most obvious behaviour. A useful specification explores what happens around that path: alternative happy paths, boundary conditions, edge cases, validation rules, error conditions and interactions between business rules.</p>

<p>For example, confirming that an available bottle can be ordered is necessary but unsurprising. More interesting behaviour occurs when the customer’s first choice is unavailable:</p>

<pre><code class="language-feature">Scenario: An alternative is offered when a wine has sold out

    Given an extensive wine list
    And the Sancerre "Les Baronnes" 2023 has sold out
    And Pouilly-Fumé "La Moynerie" 2023 is the closest alternative

    When the customer requests the wine list
    And asks for the Sancerre "Les Baronnes" 2023

    Then they are told that it is unavailable
    And offered the Pouilly-Fumé "La Moynerie" 2023
</code></pre>

<p>This is an alternative happy path. The customer’s original request cannot be fulfilled, but the business still provides useful behaviour. A scenario should also centre on one coherent behavioural idea. It may contain several assertions where necessary to demonstrate that behaviour, but avoid turning it into a tour through unrelated functionality.</p>

<h3 id="rule-6-prefer-concrete-examples">Rule 6: Prefer concrete examples</h3>

<p>BDD works best when business rules are demonstrated through concrete examples rather than merely restated. The wine scenario above does not say:</p>

<pre><code class="language-feature">Given a wine is unavailable
And another wine is a suitable alternative
</code></pre>

<p>It identifies particular wines. Concrete examples make scenarios easier to reason about and expose assumptions that abstract statements can conceal. Use realistic names and values where they improve comprehension, and avoid arbitrary test terminology such as <code class="language-plaintext highlighter-rouge">item1</code>, <code class="language-plaintext highlighter-rouge">userA</code> and <code class="language-plaintext highlighter-rouge">value2</code> when a meaningful example would be clearer.</p>

<p>Realism is not a goal in itself, however. Details that do not contribute to understanding the behaviour are noise. This is another application of <a href="#rule-1-simplicity-above-all">Rule 1: Simplicity above all</a>.</p>

<h3 id="rule-7-keep-important-values-visible">Rule 7: Keep important values visible</h3>

<p>Values that matter to the behaviour should normally appear explicitly in the scenario. Notice that the wine scenario establishes:</p>

<pre><code class="language-feature">And Pouilly-Fumé "La Moynerie" 2023 is the closest alternative
</code></pre>

<p>and later asserts:</p>

<pre><code class="language-feature">And offered the Pouilly-Fumé "La Moynerie" 2023
</code></pre>

<p>The expectation is visible. The reader does not need to know that some hidden fixture happens to define that wine as the closest alternative, at least in this scenario. Avoid magical values that exist only inside the step implementation.</p>

<p>There is an important exception when the setup itself is large. For example:</p>

<pre><code class="language-feature">Given an extensive wine list
</code></pre>

<p>might establish dozens or hundreds of wines, including their vintages, prices, regions, availability and relationships to suitable alternatives. Making all of that data explicit would add noise rather than meaning.</p>

<p>Use meaningful named datasets for this kind of setup, but make the values actually being tested explicit. Named datasets should provide context, not hidden expectations.</p>

<h3 id="rule-8-structure-features-around-behaviour">Rule 8: Structure features around behaviour</h3>

<p>Use features and rules to organise related behaviour rather than allowing a feature to become a long collection of loosely related scenarios. A feature can contain scenarios directly and can also contain rules. Rules can group scenarios describing a particular business rule and can have their own backgrounds. For example:</p>

<pre><code class="language-feature">Feature: Ordering wine

    Rule: Wine availability
        ...

    Rule: Alternative recommendations
        ...

    Rule: Age restrictions
        ...
</code></pre>

<p>Use this hierarchy when the behaviour naturally divides into meaningful groups. Names are part of the specification too. <code class="language-plaintext highlighter-rouge">Scenario: Unavailable wine 1</code> says very little, whereas <code class="language-plaintext highlighter-rouge">Scenario: An alternative is offered when a wine has sold out</code> identifies the behaviour that makes the example interesting. A reader scanning only the feature, rule and scenario headings should still get a useful overview of the behaviour being specified.</p>

<h3 id="rule-9-use-backgrounds-to-remove-common-setup">Rule 9: Use backgrounds to remove common setup</h3>

<p>Backgrounds are a useful way to subtract repeated setup from scenarios. A feature background can establish context common to the feature, while a rule background can establish context shared only by the scenarios within that rule. For example:</p>

<pre><code class="language-feature">Feature: Ordering wine

    Background:
        Given an extensive wine list

    Rule: Alternative recommendations

        Background:
            Given alternative recommendations are enabled

        Scenario: An alternative is offered when a wine has sold out
            ...
</code></pre>

<p>Put common setup at the narrowest appropriate level. Do not move setup into a background merely to make scenarios shorter: a background should represent genuine shared context. If understanding a scenario requires repeatedly looking elsewhere to discover important values, the abstraction has probably removed meaning rather than noise.</p>

<h3 id="rule-10-use-tables-to-express-variations">Rule 10: Use tables to express variations</h3>

<p>When several examples demonstrate the same behaviour using different values, avoid repeating almost identical scenarios. Use an Examples or Where table to make the common behaviour visible and emphasise what varies. For example:</p>

<pre><code class="language-feature">Scenario: An alternative is offered when a wine has sold out

    Given an extensive wine list
    And $requestedWine has sold out
    And $alternativeWine is the closest alternative

    When the customer requests the wine list
    And asks for $requestedWine

    Then they are told that it is unavailable
    And offered $alternativeWine

    Where:
        requestedWine                 | alternativeWine
        Sancerre "Les Baronnes" 2023 | Pouilly-Fumé "La Moynerie" 2023
        ...                           | ...
</code></pre>

<p>The scenario describes the behaviour once and the table contains the examples. This is another application of simplicity: subtract the repetitive structure and emphasise the meaningful differences.</p>

<h3 id="rule-11-use-yaddas-feature-syntax-expressively">Rule 11: Use Yadda’s feature syntax expressively</h3>

<p>Yadda does not require every step to begin with <code class="language-plaintext highlighter-rouge">Given</code>, <code class="language-plaintext highlighter-rouge">When</code> or <code class="language-plaintext highlighter-rouge">Then</code>, but that does not mean you should avoid them. They are useful when they make the scenario read naturally, as they do in many of the examples above. The important point is not to be constrained by them. Use <code class="language-plaintext highlighter-rouge">Given</code>, <code class="language-plaintext highlighter-rouge">When</code>, <code class="language-plaintext highlighter-rouge">Then</code>, <code class="language-plaintext highlighter-rouge">And</code>, <code class="language-plaintext highlighter-rouge">But</code>, bullet points or ordinary sentences according to what communicates the behaviour most naturally.</p>

<p>For example, a list may sometimes be clearer than a sequence of artificial <code class="language-plaintext highlighter-rouge">And</code> steps:</p>

<pre><code class="language-feature">Given the wine list includes:

    - Sancerre "Les Baronnes" 2023
    - Pouilly-Fumé "La Moynerie" 2023
    - Chablis "Saint Martin" 2022
</code></pre>

<p>Yadda also supports multiline content associated with the preceding step, including tables, CSV, code blocks, structured text and even ASCII diagrams. These can be useful when complicated input or an assertion is clearer as a single structured block than as many individual steps. Use them selectively because they usually require additional parsing in the implementation, so the improvement in readability should justify that complexity.</p>

<h3 id="rule-12-refactor-the-specification-continuously">Rule 12: Refactor the specification continuously</h3>

<p>Features are not finished merely because they execute. As the specification grows, better language and better abstractions will emerge, so regularly look for repetitive scenarios, duplicated steps, inconsistent or obsolete terminology, unnecessarily technical language, awkward grammar, hidden values, overly broad backgrounds and opportunities to make interesting differences more prominent.</p>

<p>When you discover better terminology for a business concept, apply it retrospectively. Do not preserve inferior language simply because a matching step implementation already exists. Good executable specifications evolve alongside the understanding of the domain.</p>

<h2 id="implementing-yadda">Implementing Yadda</h2>

<p>The implementation exists to support the specification, not to dictate it. The techniques below are intended to make natural, expressive features practical without allowing the implementation to become unmanageable.</p>

<h3 id="rule-1-organise-steps-into-libraries">Rule 1: Organise steps into libraries</h3>

<p>A single step library may be convenient initially, but it becomes increasingly difficult to manage as the suite grows. Split steps into coherent libraries based on domain, capability or application layer.</p>

<p>Yadda’s library resolution provides another useful property: where otherwise ambiguous step patterns exist in different libraries, Yadda prefers the library that was most recently used. This means similar business-language steps can have different implementations in different libraries without necessarily causing a step clash. Use this deliberately rather than relying on accidental precedence.</p>

<h3 id="rule-2-load-only-the-libraries-you-need">Rule 2: Load only the libraries you need</h3>

<p>For small projects, loading all step libraries is usually the simplest approach and there is little benefit in adding extra selection logic.</p>

<p>As the suite grows, however, selectively loading libraries can become useful. Yadda annotations can be used to select the libraries required by a particular specification, keeping the available step vocabulary scoped to the behaviour being exercised and reducing the likelihood that unrelated libraries will introduce step clashes.</p>

<p>Treat this as a technique for managing larger suites rather than something every Yadda project needs from the outset.</p>

<h3 id="rule-3-reuse-specifications-across-interfaces">Rule 3: Reuse specifications across interfaces</h3>

<p>Good business language is independent of the mechanism used to exercise the application. The same specification:</p>

<pre><code class="language-feature">When the customer requests the wine list
And asks for the Sancerre "Les Baronnes" 2023

Then they are told that it is unavailable
And offered the Pouilly-Fumé "La Moynerie" 2023
</code></pre>

<p>could be exercised through an API or through a user interface. Different libraries can provide different implementations of those steps while the business specification remains unchanged.</p>

<p>If a scenario needs substantial rewriting merely because it is being exercised through another interface, implementation language may have leaked into the specification. See <a href="#rule-2-speak-the-language-of-the-business">Rule 2: Speak the language of the business</a>.</p>

<h3 id="rule-4-prefer-dictionaries-to-regular-expressions">Rule 4: Prefer dictionaries to regular expressions</h3>

<p>Avoid embedding anonymous regular-expression captures throughout step patterns. Prefer named Yadda dictionary terms. For example:</p>

<div class="language-javascript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="dl">"</span><span class="s2">When the customer visits $Restaurant</span><span class="dl">"</span>
</code></pre></div></div>

<p>communicates considerably more than a pattern containing an anonymous regular expression intended to capture <code class="language-plaintext highlighter-rouge">The Ivy</code>, while:</p>

<div class="language-javascript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="dl">"</span><span class="s2">And asks for $Wine</span><span class="dl">"</span>
</code></pre></div></div>

<p>makes the purpose of the captured value immediately apparent.</p>

<p>Dictionary terms make patterns easier to read and more specific, reducing the likelihood of unrelated steps matching the same text. Use meaningful domain names for dictionary terms rather than generic captures wherever possible. This supports <a href="#rule-4-make-the-automation-fit-the-language">Rule 4: Make the automation fit the language</a>.</p>

<h3 id="rule-5-use-dictionaries-as-a-domain-vocabulary">Rule 5: Use dictionaries as a domain vocabulary</h3>

<p>Dictionaries are more than a readable alternative to inline regular expressions. They provide a vocabulary for values that occur in the domain. In the wine example, terms such as <code class="language-plaintext highlighter-rouge">$Restaurant</code>, <code class="language-plaintext highlighter-rouge">$Wine</code>, <code class="language-plaintext highlighter-rouge">$Vintage</code>, <code class="language-plaintext highlighter-rouge">$Region</code>, <code class="language-plaintext highlighter-rouge">$Price</code> and <code class="language-plaintext highlighter-rouge">$Quantity</code> tell the reader what kind of value a step pattern expects.</p>

<p>As the suite develops, the dictionary becomes part of the implementation vocabulary of the domain. This improves readability and consistency while also making step matching more specific.</p>

<h3 id="rule-6-convert-values-at-the-dictionary-boundary">Rule 6: Convert values at the dictionary boundary</h3>

<p>Values captured from feature text frequently need converting before they are useful to the implementation, and that conversion should happen in the dictionary where possible. For example, a <code class="language-plaintext highlighter-rouge">$Quantity</code> dictionary term might match numeric text but use its converter to pass a JavaScript number to the step rather than the original string. Similarly, a <code class="language-plaintext highlighter-rouge">$Price</code> might parse its textual representation into whatever type the application uses to represent money.</p>

<p>Keeping conversion at the dictionary boundary avoids repetitive parsing in individual step implementations and ensures that the same domain concept is interpreted consistently throughout the suite.</p>

<h3 id="rule-7-support-natural-grammar">Rule 7: Support natural grammar</h3>

<p>Do not allow implementation convenience to force grammatically incorrect or unnatural steps. Natural English sometimes requires legitimate variations of the same pattern, with the choice between <code class="language-plaintext highlighter-rouge">a</code> and <code class="language-plaintext highlighter-rouge">an</code> being a simple example.</p>

<p>A small regular expression can be appropriate where the alternatives are simple and the resulting pattern remains readable. Alternatively, Yadda supports step aliases by allowing an array of step patterns to be supplied instead of a single pattern. Choose whichever keeps the implementation understandable while allowing the specification to remain natural. See <a href="#rule-4-make-the-automation-fit-the-language">Rule 4: Make the automation fit the language</a>.</p>

<h3 id="rule-8-do-not-optimise-for-step-reuse">Rule 8: Do not optimise for step reuse</h3>

<p>Step reuse is useful, but it is not the objective. Do not distort two distinct business concepts into a generic step merely because their implementations happen to be similar. If the business naturally describes two behaviours differently, allow the steps to be different and share implementation code underneath them where appropriate.</p>

<p>Conversely, do not accumulate arbitrary synonyms for precisely the same domain concept. If the business has settled terminology, use it consistently. Reuse code where useful and reuse language where meaningful.</p>

<h3 id="rule-9-use-context-to-support-natural-references">Rule 9: Use context to support natural references</h3>

<p>The Yadda context can allow subsequent steps to refer naturally to things established earlier. For example:</p>

<pre><code class="language-feature">Given Alice has requested the wine list
When she selects the Sancerre "Les Baronnes" 2023
Then she is told that it is unavailable
</code></pre>

<p>The first step can place Alice into the context, allowing subsequent implementations to resolve <code class="language-plaintext highlighter-rouge">she</code> naturally. This can be considerably clearer than repeatedly naming every object or person.</p>

<p>Only do this when the reference is unambiguous. If several customers have been introduced, <code class="language-plaintext highlighter-rouge">she</code> may no longer be clear; similarly, if several wines have been mentioned, <code class="language-plaintext highlighter-rouge">it</code> may be ambiguous. The context should support natural language, not create hidden state that the reader has to reconstruct.</p>

<h3 id="rule-10-keep-large-test-worlds-behind-meaningful-names">Rule 10: Keep large test worlds behind meaningful names</h3>

<p>Some behaviour requires substantial setup, and constructing the entire application world through dozens of steps would obscure the behaviour being tested. In these cases, maintain named fixtures or datasets that hide irrelevant detail. For example:</p>

<pre><code class="language-feature">Given an extensive wine list
</code></pre>

<p>might establish a large catalogue containing wines from many regions and vintages, together with prices, stock levels and relationships to suitable alternatives.</p>

<p>The scenario can then customise the particular values that matter:</p>

<pre><code class="language-feature">Given an extensive wine list
And the Sancerre "Les Baronnes" 2023 has sold out
And Pouilly-Fumé "La Moynerie" 2023 is the closest alternative
</code></pre>

<p>The fixture supplies the uninteresting world while the scenario makes the interesting facts explicit. See <a href="#rule-7-keep-important-values-visible">Rule 7: Keep important values visible</a>.</p>

<h3 id="rule-11-organise-supporting-code-as-the-suite-grows">Rule 11: Organise supporting code as the suite grows</h3>

<p>A Yadda implementation may begin with a handful of steps but can grow into a substantial body of test infrastructure. Separate different responsibilities rather than allowing everything to accumulate alongside the step definitions. A mature suite may have distinct areas for libraries, dictionaries and converters, parsers, fixtures and named datasets, assertion helpers and utility modules.</p>

<p>The exact directory structure is less important than maintaining clear boundaries. Rich step content may require parsers and shared business assertions may warrant dedicated helpers, but these concerns should not make the step libraries themselves difficult to navigate.</p>

<h3 id="rule-12-refactor-the-implementation-continuously">Rule 12: Refactor the implementation continuously</h3>

<p>Step implementations need the same ongoing attention as the specification. As the suite grows, look for duplicate or overly broad step patterns, step clashes, opportunities for dictionary terms, repeated conversion or parsing logic, libraries that have become too large, inappropriate dependencies between libraries and implementation code that has started to dictate feature language.</p>

<p>Failures should remain useful, so where an assertion would otherwise produce a cryptic technical error, add enough domain context to make the violated expectation clear. Yadda’s development annotations can also help while working on the suite: pending steps allow behaviour to be written ahead of its implementation or temporarily disabled, while only steps allow work to be focused on a particular step without running the entire suite.</p>

<p>Refactoring should work in both directions. Improvements in the implementation may enable better feature language, while improvements in feature language may expose implementation abstractions that no longer make sense.</p>]]></content><author><name>Stephen Cresswell</name></author><category term="BDD" /><category term="Yadda" /><category term="Software Testing" /><category term="Generative AI" /><category term="AI Agents" /><summary type="html"><![CDATA[Yadda 3 makes it easier to write executable specifications in the natural language of the business. Here are the principles and practices I use to keep those specifications simple, expressive and useful, whether they're being read and written by humans or agents.]]></summary></entry><entry><title type="html">Good mechanisms for Drizzle: Announcing drizzle-transact and drizzle-explain</title><link href="http://www.stephen-cresswell.com/2026/08/23/Good-mechanisms-for-Drizzle-announcing-drizzle-transact-and-drizzle-explain.html" rel="alternate" type="text/html" title="Good mechanisms for Drizzle: Announcing drizzle-transact and drizzle-explain" /><published>2026-08-23T00:00:00+00:00</published><updated>2026-08-23T00:00:00+00:00</updated><id>http://www.stephen-cresswell.com/2026/08/23/Good-mechanisms-for-Drizzle-announcing-drizzle-transact-and-drizzle-explain</id><content type="html" xml:base="http://www.stephen-cresswell.com/2026/08/23/Good-mechanisms-for-Drizzle-announcing-drizzle-transact-and-drizzle-explain.html"><![CDATA[<p>There is a line from Jeff Bezos that I keep coming back to: good intentions don’t work, good mechanisms do.</p>

<p>The point is that if something repeatedly goes wrong, asking people to be more careful is rarely a satisfactory answer. People forget things, take shortcuts, misunderstand conventions and make mistakes. Good intentions also don’t scale particularly well. You have to communicate them to everyone who works on the code, communicate them well enough that they understand not just what to do but why, and then rely on that knowledge being retained. Even when the rule itself is easy to explain, its importance may depend on experience and context that is much harder to transfer.</p>

<p>A better solution is usually to change the system so that doing the right thing is the easiest option, or so that doing the wrong thing becomes immediately visible. The mechanism carries the knowledge instead of relying on every developer having it. There are two places where I think the Drizzle ORM ecosystem relies a little too heavily on good intentions, so I built libraries to address them.</p>

<h2 id="transactions-are-too-easy-to-escape">Transactions are too easy to escape</h2>

<p>Drizzle requires the transaction object to be explicitly passed to anything that participates in a transaction:</p>

<div class="language-ts highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">const</span> <span class="nx">order</span> <span class="o">=</span> <span class="k">await</span> <span class="nx">db</span><span class="p">.</span><span class="nx">transaction</span><span class="p">(</span><span class="k">async</span> <span class="p">(</span><span class="nx">tx</span><span class="p">)</span> <span class="o">=&gt;</span> <span class="p">{</span>
  <span class="k">return</span> <span class="nx">createOrder</span><span class="p">(</span><span class="nx">tx</span><span class="p">);</span>
<span class="p">});</span>

<span class="k">async</span> <span class="kd">function</span> <span class="nx">createOrder</span><span class="p">(</span><span class="nx">tx</span><span class="p">:</span> <span class="nx">DbTransaction</span><span class="p">)</span> <span class="p">{</span>
  <span class="kd">const</span> <span class="p">[</span><span class="nx">order</span><span class="p">]</span> <span class="o">=</span> <span class="k">await</span> <span class="nx">tx</span><span class="p">.</span><span class="nx">insert</span><span class="p">(</span><span class="nx">orders</span><span class="p">).</span><span class="nx">values</span><span class="p">(...).</span><span class="nx">returning</span><span class="p">();</span>
  <span class="k">await</span> <span class="nx">createOrderItems</span><span class="p">(</span><span class="nx">tx</span><span class="p">,</span> <span class="nx">order</span><span class="p">.</span><span class="nx">id</span><span class="p">);</span>
  <span class="k">return</span> <span class="nx">order</span><span class="p">;</span>
<span class="p">}</span>

<span class="k">async</span> <span class="kd">function</span> <span class="nx">createOrderItems</span><span class="p">(</span><span class="nx">tx</span><span class="p">:</span> <span class="nx">DbTransaction</span><span class="p">,</span> <span class="nx">orderId</span><span class="p">:</span> <span class="kr">number</span><span class="p">)</span> <span class="p">{</span>
  <span class="k">await</span> <span class="nx">tx</span><span class="p">.</span><span class="nx">insert</span><span class="p">(</span><span class="nx">orderItems</span><span class="p">).</span><span class="nx">values</span><span class="p">(...);</span>
<span class="p">}</span>
</code></pre></div></div>

<p>Passing <code class="language-plaintext highlighter-rouge">tx</code> around is slightly annoying, but that isn’t the important problem. The important problem is that <code class="language-plaintext highlighter-rouge">db</code> still exists. Somewhere further down the call stack it is very easy to use <code class="language-plaintext highlighter-rouge">db.insert(...)</code> rather than <code class="language-plaintext highlighter-rouge">tx.insert(...)</code>. The query works perfectly well, but it is no longer participating in the transaction.</p>

<p>For a read that may not matter, but for a sequence of related writes it matters a great deal. One write can commit while another rolls back, leaving the database in a state the application never intended. Nothing about the code makes this mistake especially conspicuous: it compiles, functional tests may well pass, and the problem only becomes apparent when something fails at exactly the wrong point.</p>

<p>You can document the rule that database access inside a transaction must always use <code class="language-plaintext highlighter-rouge">tx</code>, but that brings us straight back to good intentions. Every developer has to know the rule, understand why it matters and recognise all the places where it applies. As the team changes and the codebase grows, that knowledge has to be communicated and retained.</p>

<h3 id="drizzle-transact">drizzle-transact</h3>

<p><a href="https://www.npmjs.com/package/drizzle-transact"><code class="language-plaintext highlighter-rouge">drizzle-transact</code></a> takes a different approach. The raw Drizzle instance is wrapped during application setup and is not exported for general use. Database access happens through functions such as <code class="language-plaintext highlighter-rouge">withTransaction</code> and <code class="language-plaintext highlighter-rouge">newTransaction</code>, while the current transaction is held using Node’s <code class="language-plaintext highlighter-rouge">AsyncLocalStorage</code> so functions further down the call stack can automatically participate in it:</p>

<div class="language-ts highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">import</span> <span class="p">{</span> <span class="nx">newTransaction</span><span class="p">,</span> <span class="nx">withTransaction</span> <span class="p">}</span> <span class="k">from</span> <span class="dl">'</span><span class="s1">./db</span><span class="dl">'</span><span class="p">;</span>

<span class="kd">const</span> <span class="nx">order</span> <span class="o">=</span> <span class="k">await</span> <span class="nx">newTransaction</span><span class="p">(()</span> <span class="o">=&gt;</span> <span class="nx">createOrder</span><span class="p">());</span>

<span class="k">async</span> <span class="kd">function</span> <span class="nx">createOrder</span><span class="p">()</span> <span class="p">{</span>
  <span class="k">return</span> <span class="nx">withTransaction</span><span class="p">(</span><span class="k">async</span> <span class="p">(</span><span class="nx">tx</span><span class="p">)</span> <span class="o">=&gt;</span> <span class="p">{</span>
    <span class="kd">const</span> <span class="p">[</span><span class="nx">order</span><span class="p">]</span> <span class="o">=</span> <span class="k">await</span> <span class="nx">tx</span><span class="p">.</span><span class="nx">insert</span><span class="p">(</span><span class="nx">orders</span><span class="p">).</span><span class="nx">values</span><span class="p">(...).</span><span class="nx">returning</span><span class="p">();</span>
    <span class="k">await</span> <span class="nx">createOrderItems</span><span class="p">(</span><span class="nx">order</span><span class="p">.</span><span class="nx">id</span><span class="p">);</span>
    <span class="k">return</span> <span class="nx">order</span><span class="p">;</span>
  <span class="p">});</span>
<span class="p">}</span>

<span class="k">async</span> <span class="kd">function</span> <span class="nx">createOrderItems</span><span class="p">(</span><span class="nx">orderId</span><span class="p">:</span> <span class="kr">number</span><span class="p">)</span> <span class="p">{</span>
  <span class="k">await</span> <span class="nx">withTransaction</span><span class="p">(</span><span class="k">async</span> <span class="p">(</span><span class="nx">tx</span><span class="p">)</span> <span class="o">=&gt;</span> <span class="p">{</span>
    <span class="k">await</span> <span class="nx">tx</span><span class="p">.</span><span class="nx">insert</span><span class="p">(</span><span class="nx">orderItems</span><span class="p">).</span><span class="nx">values</span><span class="p">(...);</span>
  <span class="p">});</span>
<span class="p">}</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">createOrderItems</code> doesn’t need to know that <code class="language-plaintext highlighter-rouge">createOrder</code> started the transaction. <code class="language-plaintext highlighter-rouge">withTransaction</code> simply joins the transaction that is already active. This removes the need to pass <code class="language-plaintext highlighter-rouge">tx</code> through layers of otherwise unrelated business logic, which is useful in itself, but the main reason for doing it is safety: application code doesn’t have a convenient non-transactional database handle available to accidentally use.</p>

<p>The model is deliberately similar to transaction propagation in Spring. The underlying <code class="language-plaintext highlighter-rouge">transact</code> function supports:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">Required</code> - join the current transaction, or create one</li>
  <li><code class="language-plaintext highlighter-rouge">RequiresNew</code> - always create an independent transaction</li>
  <li><code class="language-plaintext highlighter-rouge">Nested</code> - use a savepoint within the current transaction</li>
  <li><code class="language-plaintext highlighter-rouge">RequiresExisting</code> - join the current transaction, or throw if there isn’t one</li>
  <li><code class="language-plaintext highlighter-rouge">Never</code> - require that no transaction is active</li>
</ul>

<p>There are also shorthand functions for the common cases. I particularly like <code class="language-plaintext highlighter-rouge">RequiresExisting</code>: if a function such as <code class="language-plaintext highlighter-rouge">deductStock</code> is only safe when called as part of a larger transaction, that constraint can be expressed in code. Calling it incorrectly then fails immediately rather than relying on somebody knowing, and remembering, the convention.</p>

<h2 id="why-not-use-drizzle-transactional">Why not use drizzle-transactional?</h2>

<p>There is already another library solving a similar problem: <a href="https://www.npmjs.com/package/drizzle-transactional"><code class="language-plaintext highlighter-rouge">drizzle-transactional</code></a>. I looked at it before deciding to write <code class="language-plaintext highlighter-rouge">drizzle-transact</code>, and it is worth considering. Its API wasn’t quite what I wanted, though. I preferred explicit transaction propagation to its hook-based model, and although I initially liked its <code class="language-plaintext highlighter-rouge">@Transactional</code> decorator, implementing something similar required proxying the Drizzle client and routing calls invisibly between the active transaction and the underlying client. It worked, but felt more magical than I wanted for something whose purpose is to make transactional behaviour clear.</p>

<p>The other difference is dependencies. <code class="language-plaintext highlighter-rouge">drizzle-transactional</code> depends on <code class="language-plaintext highlighter-rouge">zod</code>, <code class="language-plaintext highlighter-rouge">reflect-metadata</code> and <code class="language-plaintext highlighter-rouge">drizzle-orm</code>, whereas <code class="language-plaintext highlighter-rouge">drizzle-transact</code> has no production dependencies and uses Node’s <code class="language-plaintext highlighter-rouge">AsyncLocalStorage</code> plus the Drizzle instance the application already has. Dependencies bring upgrade work, security noise and additional supply-chain exposure, so when a small infrastructure library can reasonably avoid them, I think it should.</p>

<h2 id="testable-query-plans">Testable query plans</h2>

<p>Consider this query:</p>

<div class="language-ts highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nx">db</span><span class="p">.</span><span class="nx">select</span><span class="p">()</span>
  <span class="p">.</span><span class="k">from</span><span class="p">(</span><span class="nx">reservations</span><span class="p">)</span>
  <span class="p">.</span><span class="nx">where</span><span class="p">(</span><span class="nx">eq</span><span class="p">(</span><span class="nx">reservations</span><span class="p">.</span><span class="nx">roomId</span><span class="p">,</span> <span class="nx">roomId</span><span class="p">));</span>
</code></pre></div></div>

<p>Suppose <code class="language-plaintext highlighter-rouge">reservations</code> contains five million rows and there is no index on <code class="language-plaintext highlighter-rouge">room_id</code>. The query is perfectly correct, but PostgreSQL has little choice other than to scan the table. That may be invisible during development: against a small local database the query is fast, its functional tests pass and nothing suggests there is a problem. It only becomes expensive once it runs against realistic volumes.</p>

<p>There is another version of the same problem where the schema is correct and the necessary indexes exist, but the optimiser’s statistics no longer represent the data particularly well. PostgreSQL chooses plans using estimates about things such as predicate selectivity and the number of rows produced by each operation. If those estimates are badly wrong, it can choose a plan that looks sensible for the data it thinks it has but performs badly against the data it actually has. In both cases, functional correctness tells us nothing useful because the query still returns the right answer.</p>

<p>The usual advice is to inspect important queries with <code class="language-plaintext highlighter-rouge">EXPLAIN</code>, but that is another good-intentions solution. It relies on developers identifying which queries deserve inspection, remembering to inspect them, understanding the resulting query plan and doing so against representative data. Query performance is also particularly easy to overlook in JavaScript and TypeScript teams, where many developers are weighted more towards frontend development and simply haven’t accumulated years of database experience. That isn’t a criticism, but it does make database performance a poor thing to depend on individual knowledge and memory for.</p>

<h3 id="drizzle-explain">drizzle-explain</h3>

<p><a href="https://www.npmjs.com/package/drizzle-explain"><code class="language-plaintext highlighter-rouge">drizzle-explain</code></a> makes query plans testable. It executes a Drizzle query using <code class="language-plaintext highlighter-rouge">EXPLAIN (ANALYZE, FORMAT JSON)</code> and checks the resulting query plan against configurable constraints:</p>

<div class="language-ts highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">import</span> <span class="p">{</span> <span class="nx">createExplain</span> <span class="p">}</span> <span class="k">from</span> <span class="dl">'</span><span class="s1">drizzle-explain</span><span class="dl">'</span><span class="p">;</span>
<span class="k">import</span> <span class="p">{</span> <span class="nx">postgresDriver</span> <span class="p">}</span> <span class="k">from</span> <span class="dl">'</span><span class="s1">drizzle-explain/postgres</span><span class="dl">'</span><span class="p">;</span>

<span class="kd">const</span> <span class="nx">explain</span> <span class="o">=</span> <span class="nx">createExplain</span><span class="p">(</span>
  <span class="nx">postgresDriver</span><span class="p">(</span><span class="nx">pool</span><span class="p">),</span>
  <span class="p">{</span>
    <span class="na">maxCost</span><span class="p">:</span> <span class="mi">100</span><span class="p">,</span>
    <span class="na">rowEstimateTolerance</span><span class="p">:</span> <span class="mi">10</span><span class="p">,</span>
  <span class="p">},</span>
<span class="p">);</span>

<span class="kd">const</span> <span class="nx">analysis</span> <span class="o">=</span> <span class="k">await</span> <span class="nx">explain</span><span class="p">(</span>
  <span class="p">(</span><span class="nx">db</span><span class="p">)</span> <span class="o">=&gt;</span> <span class="nx">findReservationsByRoom</span><span class="p">(</span><span class="nx">db</span><span class="p">,</span> <span class="nx">roomId</span><span class="p">),</span>
<span class="p">);</span>

<span class="nx">assert</span><span class="p">.</span><span class="nx">ok</span><span class="p">(</span><span class="nx">analysis</span><span class="p">.</span><span class="nx">passed</span><span class="p">,</span> <span class="nx">analysis</span><span class="p">.</span><span class="nx">message</span><span class="p">);</span>
</code></pre></div></div>

<p>Queries are executed inside a transaction which is always rolled back, so writes can also be analysed without leaving test data behind. The library currently checks three aspects of the query plan: estimated cost, the accuracy of row estimates and optionally the presence of disallowed operations.</p>

<p>A missing index will often produce a dramatic increase in the optimiser’s estimated cost. A deliberately low cost threshold provides a useful tripwire: if a query crosses it, somebody needs to look at the plan and either improve the query or explicitly accept a higher cost for that particular case.</p>

<p>The second check compares estimated and actual row counts throughout the plan. Poor row estimates are an important cause of bad plan selection. Measuring the ratio rather than the absolute difference also means that normal growth in the amount of data doesn’t inherently break the test. What matters is whether the shape of the data has changed enough that the optimiser’s model of it is becoming inaccurate.</p>

<p>Finally, individual plan operations can be disallowed. If, for example, a query should never perform a sequential scan of a particular table, the test can say so directly. When something fails, the analysis includes a rendered version of the query plan showing the offending node:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>✘ cost 62431 exceeds limit 100

Seq Scan on reservations  (cost=0..62431 rows=10 actual=10)  ✘ cost 62431 &gt; 100
  Filter: (room_id = 42)
</code></pre></div></div>

<p>One thing the library deliberately does not test is execution time. Timing depends on hardware, cache state and whatever else happens to be running on the machine, so a test that passes on a developer’s laptop and intermittently fails in CI isn’t particularly useful. Cost and row-estimate accuracy describe the query plan rather than the machine running it, which makes them much better candidates for automated tests.</p>

<h2 id="the-test-data-matters">The test data matters</h2>

<p>There is an important limitation to all of this: <code class="language-plaintext highlighter-rouge">EXPLAIN</code> can only tell you about the data it is given, and the optimiser doesn’t make decisions based purely on the number of rows in a table. Distribution matters. A hotel booking system, for example, may have considerably more summer reservations than winter reservations and some room grades may be much more popular than others. Seed a database with uniformly distributed test data and the resulting query plans may bear little resemblance to production.</p>

<p>For that reason the <code class="language-plaintext highlighter-rouge">drizzle-explain</code> repository contains a worked example using <a href="https://github.com/drizzle-team/drizzle-orm/tree/main/drizzle-seed"><code class="language-plaintext highlighter-rouge">drizzle-seed</code></a> to construct a production-shaped hotel booking dataset rather than simply generating a large number of random rows. This is probably the most important prerequisite for useful query-plan testing. You don’t necessarily need a copy of production, but you do need data with approximately the same characteristics.</p>

<p><code class="language-plaintext highlighter-rouge">drizzle-explain</code> currently supports PostgreSQL and MariaDB. SQLite’s <code class="language-plaintext highlighter-rouge">EXPLAIN QUERY PLAN</code> doesn’t expose cost or estimated row counts, so the checks the library is built around aren’t available there. As with <code class="language-plaintext highlighter-rouge">drizzle-transact</code>, the library adds no production dependencies: you provide the database client and the appropriate driver adapts its query plans into the common representation used by the analyser.</p>

<h2 id="the-common-idea">The common idea</h2>

<p>The two libraries solve different problems, but they came from the same observation. With transactions, we rely on developers remembering to use the right database handle throughout the call stack. With query performance, we rely on them remembering to inspect query plans, understanding them and doing so against representative data. Neither is something I want to depend on individual knowledge and memory for.</p>

<p><code class="language-plaintext highlighter-rouge">drizzle-transact</code> makes transaction propagation the normal way to access the database, while <code class="language-plaintext highlighter-rouge">drizzle-explain</code> turns query-plan expectations into executable tests. In both cases, the mechanism captures knowledge that would otherwise have to be repeatedly communicated and remembered, and applies it consistently. That is what I mean by a good mechanism.</p>

<h2 id="how-i-built-them">How I built them</h2>

<p>I built both libraries using Claude Code (Opus 4.8), following almost the same process each time. I first worked through the problem and API design with Claude, then had it write the README before any implementation. That README became the specification and source of truth for the rest of the work.</p>

<p>Claude then broke the implementation into GitHub issues that could be worked on in parallel using separate worktrees. <code class="language-plaintext highlighter-rouge">CLAUDE.md</code> and <code class="language-plaintext highlighter-rouge">CONTRIBUTING.md</code> contained the standing instructions, coding conventions and development rules. I focused mainly on the design and behaviour, then reviewed the implementation in detail towards the end.</p>

<p>Parallel development did introduce some drift. In <code class="language-plaintext highlighter-rouge">drizzle-explain</code>, the PostgreSQL and MariaDB drivers and examples developed slightly different approaches to the same behaviour and needed reconciling afterwards. Claude also introduced a normalised query-plan representation between the database-specific drivers and the core analyser, and identified the limitations of SQLite support from the information exposed by <code class="language-plaintext highlighter-rouge">EXPLAIN QUERY PLAN</code>.</p>

<p>Each library took roughly half a day of elapsed time to build, although I was doing other things at the same time. Most of my involvement was in defining the behaviour, refining the API and reviewing the result rather than writing the implementation itself.</p>

<p>Both libraries are MIT licensed and available on npm:</p>

<ul>
  <li><a href="https://www.npmjs.com/package/drizzle-transact"><code class="language-plaintext highlighter-rouge">drizzle-transact</code></a></li>
  <li><a href="https://www.npmjs.com/package/drizzle-explain"><code class="language-plaintext highlighter-rouge">drizzle-explain</code></a></li>
</ul>]]></content><author><name>Stephen Cresswell</name></author><category term="Drizzle ORM" /><category term="TypeScript" /><category term="JavaScript" /><category term="PostgreSQL" /><category term="MariaDB" /><category term="Transactions" /><category term="Query Plans" /><category term="Query Optimisation" /><category term="Software Engineering" /><category term="Claude Code" /><category term="AI-Assisted Development" /><summary type="html"><![CDATA[Announcing `drizzle-transact` and `drizzle-explain`: two small libraries that turn good intentions into good mechanisms.]]></summary></entry><entry><title type="html">Yadda 3.0.0: BDD in the Age of AI Agents</title><link href="http://www.stephen-cresswell.com/2026/08/15/Yadda-3.0.0-BDD-in-the-Age-of-AI-Agents.html" rel="alternate" type="text/html" title="Yadda 3.0.0: BDD in the Age of AI Agents" /><published>2026-08-15T00:00:00+00:00</published><updated>2026-08-15T00:00:00+00:00</updated><id>http://www.stephen-cresswell.com/2026/08/15/Yadda-3.0.0-BDD-in-the-Age-of-AI-Agents</id><content type="html" xml:base="http://www.stephen-cresswell.com/2026/08/15/Yadda-3.0.0-BDD-in-the-Age-of-AI-Agents.html"><![CDATA[<p>I’ve just published <a href="https://www.npmjs.com/package/yadda">Yadda 3.0.0</a> to npm.</p>

<p>For anyone unfamiliar with it, <a href="https://github.com/acuminous/yadda">Yadda</a> is a Behaviour Driven Development (BDD) library for JavaScript. Like Cucumber, it maps ordinary language specifications to executable code, but it was designed from the ground up to be much less prescriptive about how those specifications are written.</p>

<p>That means that instead of writing something like:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Given a university, The University of East Anglia
And The University of East Anglia offers a degree course in Computer Science with entry requirements of ABB
And an A-Level graduate, Steve
And Steve has a D in Physics
And Steve has a D in Maths
When Steve applies to study Computer Science at The University of Bouvet Island
Then The University of East Anglia rejects the application
</code></pre></div></div>

<p>you can write:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>The University of East Anglia offers a degree course in Computer Science
The entry requirements for which are ABB
Steve is an A-Level graduate
With a D in Physics
And a D in Maths
When Steve applies to study Computer Science at The University of East Anglia
They reject his application
</code></pre></div></div>

<p>Both are executable specifications. I find the second considerably easier to read.</p>

<h2 id="whats-changed-in-yadda-3">What’s changed in Yadda 3?</h2>

<p>Most of Yadda 3.0 is a modernisation exercise.</p>

<p>Yadda has been around for a long time, and the repository had accumulated integrations and tooling for parts of the JavaScript ecosystem that are now themselves historical curiosities. Yadda 3 is Node-only, removes browser bundling and obsolete integrations such as CasperJS, PhantomJS, Bower and Component, moves the test suite to <code class="language-plaintext highlighter-rouge">node:test</code>, adopts Biome and lefthook, modernises the source to ES6 syntax, and adds current examples including Playwright and Puppeteer. It also now ships TypeScript definitions.</p>

<p>All useful, but not especially interesting to write about. There are two things about the release that I think are much more significant.</p>

<h2 id="claude-wrote-most-of-it">Claude wrote most of it</h2>

<p>I modernised Yadda using Claude Code with Opus 4.8.</p>

<p>The <a href="https://github.com/acuminous/yadda/issues/344">Yadda 3.0 epic</a>, which was itself written by Claude, broke the work into a series of deliberately separated phases: remove obsolete functionality, update the toolchain, perform mechanical formatting separately from behavioural changes, modernise the source, explore API changes, update examples and CI, then finish the metadata, documentation and TypeScript definitions.</p>

<p>We planned each phase before implementing it, and then I largely let Claude get on with the work. It made remarkably few mistakes and, more impressively, identified some fairly subtle edge cases that would have been easy to miss during what initially looked like a mechanical modernisation. I made very few interventions.</p>

<p>One important factor was that Yadda already had a comprehensive test suite. I also deliberately avoided asking Claude to modify production code and the corresponding tests in the same step. If an agent changes both simultaneously, a green test suite becomes weaker evidence because it is free to change the definition of “correct” at the same time as the implementation. Keeping those changes separate gave Claude a much firmer external constraint.</p>

<p>From starting the work to having the package published was roughly a day of elapsed time, and I was doing other things in parallel.</p>

<p>At the beginning of this year I wrote about an experiment asking <a href="https://www.stephen-cresswell.com/2026/01/01/Why-Are-Experiences-Of-Vibe-Coding-So-Polarised.html">why experiences of vibe coding were so polarised</a>. My conclusion then was that the results depended enormously on how the agent was used. A tightly constrained and supervised Claude could produce extremely good results very quickly. Left to its own devices, it tended towards architectural drift, unnecessary code and operational debt.</p>

<p>That was only seven months ago, and the capability has moved on enormously. Even so, saying that Claude can now write this code with very little intervention barely scratches the surface of what is changing.</p>

<h2 id="coding-is-no-longer-the-bottleneck">Coding is no longer the bottleneck</h2>

<p>To appreciate where this is going, it helps to stop thinking about a single developer having a conversation with a single coding agent and instead consider several agents working in parallel.</p>

<p>There are already several ways to do this. You can simply run multiple Claude Code sessions. <a href="https://git-scm.com/docs/git-worktree">Git worktrees</a> let each agent work against an isolated working copy. Tools such as <a href="https://cmux.com">cmux</a> make running a collection of Claude sessions more manageable, while Claude Code Agent View provides another way of seeing what multiple sessions are doing and which ones need attention.</p>

<p>All of these let you build significantly faster than working serially, but I fairly quickly hit another limit: my own ability to manage the parallel work. I can comfortably keep three tasks moving at once, and sometimes four or five. Beyond that, I start losing the context of what each agent is doing, which decisions have been made, which task is waiting for me and what I need to review next.</p>

<p>At that point, the model is not overloaded and the machine is not overloaded. The bottleneck is the human coordinating the work. I’ve become convinced that good orchestration is the next important layer.</p>

<p>I’m not alone in reaching that conclusion. My colleague Marco describes almost exactly this progression in <a href="https://www.marcomark.co.uk/blog/ai-engineering-journey.html">My AI Engineering Journey</a>, moving from AI as autocomplete, through supervised and trusted agents, to parallel agents where cognitive load becomes the constraint. He is further along this journey than I am, and has responded by building Otto, an orchestration UI around Claude Code and worktrees, before moving on to agent pipelines that coordinate implementation, review, feedback and documentation.</p>

<p>The larger point is that AI-assisted software development is still moving extraordinarily quickly. Individual coding capability has improved dramatically, parallel execution is already practical, and the next constraint is increasingly the coordination of all that capability. The tools and approaches for doing so are developing just as quickly, and are now arguably even more important than the model updates.</p>

<p>Which brings me back to Yadda.</p>

<h2 id="why-update-a-bdd-library-now">Why update a BDD library now?</h2>

<p>I’ve always thought BDD was valuable for several reasons.</p>

<p>Firstly, writing requirements in ordinary language forces you to articulate the domain and, more importantly, encourages you to articulate it consistently. If you write those specifications before writing the implementation, that domain language has a habit of propagating through the codebase. The same concepts start appearing in class and function names, API definitions, database schemas, CSS classes and user interfaces. That gives the codebase a coherence that is surprisingly difficult to achieve retrospectively.</p>

<p>Secondly, executable specifications are far more accessible than conventional programmatic tests. A product manager, analyst or domain expert has a realistic chance of understanding:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>When Steve applies to study Computer Science
Then the university rejects his application
</code></pre></div></div>

<p>They are much less likely to extract the same meaning from a Jest test containing fixtures, mocks, builders and assertions.</p>

<p>Thirdly, BDD provides a useful abstraction layer for functional tests. The specification describes intent while the step implementation deals with mechanics such as selectors, navigation and browser interaction. This provides some of the same benefits as the <a href="https://www.selenium.dev/documentation/test_practices/encouraged/page_object_models/">Page Object pattern</a>: changes to the user interface can often be absorbed inside the abstraction instead of leaking through hundreds of tests.</p>

<p>There has always been a cost, though. BDD tests take longer to write initially. You need to think about the language, create reusable steps, and resist the temptation to write procedural scripts disguised as English. The payoff comes later, through better domain modelling, better communication and more maintainable functional tests. That deferred payoff has always made BDD harder to justify, but I think AI changes the economics.</p>

<h2 id="executable-specifications-are-very-good-context-for-agents">Executable specifications are very good context for agents</h2>

<p>Consider an engineering workflow that is becoming increasingly plausible.</p>

<p>Meetings are automatically transcribed and stored as GitHub discussions. Those discussions are analysed and used to update a project wiki. The wiki is mined for requirements and issues. Those issues are then picked up, implemented, reviewed and coordinated by a collection of coding agents.</p>

<p>A wiki can tell you what somebody thought the system should do. It can tell you what the system used to do. It can even tell you what an agent inferred that the system ought to do. It cannot, by itself, tell you whether the system actually does it. An executable specification can. That makes BDD much more interesting in an agentic development environment than it was before.</p>

<p>The expensive part of BDD was producing and maintaining the specification. AI makes much of that work cheap. A transcript, discussion or requirement can be transformed into a candidate specification almost trivially, with a human concentrating on whether the language and behaviour are correct rather than typing it all out. Once accepted, that specification becomes more than documentation. It becomes a contract.</p>

<p>An implementation agent can use it to understand the required behaviour. A testing agent can use it to determine what needs validating. A reviewing agent can use it to challenge an implementation. CI can continuously verify it. Because it is executable, it remains coupled to the behaviour of the software in a way that a wiki page never can.</p>

<p>There is an interesting inversion here. BDD was created partly to make software specifications more useful to humans, but executable specifications may turn out to be even more valuable when much of the software is being written by machines. The natural language gives agents rich domain context, while the executable steps ensure that the specification remains grounded in the behaviour of the system.</p>

<p>One other change (added in Yadda v3.1.0) is support for writing feature specifications as GitHub-flavoured Markdown. This makes them easier to read in the repository and, more importantly, allows them to live naturally alongside the project wiki and the other key knowledge artefacts that humans and agents use to understand the system. The same specification can now be written as:</p>

<div class="language-markdown highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="gh"># Feature: University applications</span>

<span class="gu">## Scenario: Applicant does not meet the entry requirements</span>
<span class="p">
-</span> The University of East Anglia offers a degree course in Computer Science
<span class="p">-</span> The entry requirements for which are ABB
<span class="p">-</span> Steve is an A-Level graduate
<span class="p">-</span> With a D in Physics
<span class="p">-</span> And a D in Maths
<span class="p">-</span> When Steve applies to study Computer Science at the University of East Anglia
<span class="p">-</span> They reject his application
</code></pre></div></div>

<p>It remains an executable specification, but when viewed on GitHub it looks and behaves much more like the rest of the project’s documentation.</p>

<p><a href="https://www.npmjs.com/package/yadda">Yadda 3 is available on npm</a>, and the source, documentation and examples are on <a href="https://github.com/acuminous/yadda">GitHub</a>.</p>]]></content><author><name>Stephen Cresswell</name></author><category term="Generative AI" /><category term="Claude Code" /><category term="Vibe Coding" /><category term="BDD" /><category term="Yadda" /><summary type="html"><![CDATA[Yadda 3.0.0 is out. The release modernises the JavaScript BDD library, but more interestingly, it was largely built by Claude Code and points to why executable specifications may become even more valuable in an agentic development world.]]></summary></entry><entry><title type="html">More Experiences of Vibe Coding</title><link href="http://www.stephen-cresswell.com/2026/02/15/More-Experiences-Of-Vibe-Coding.html" rel="alternate" type="text/html" title="More Experiences of Vibe Coding" /><published>2026-02-15T00:00:00+00:00</published><updated>2026-02-15T00:00:00+00:00</updated><id>http://www.stephen-cresswell.com/2026/02/15/More%20Experiences%20Of%20Vibe%20Coding</id><content type="html" xml:base="http://www.stephen-cresswell.com/2026/02/15/More-Experiences-Of-Vibe-Coding.html"><![CDATA[<p>One of the outstanding questions from my <a href="/2026/01/01/Why-Are-Experiences-of-Vibe-Coding-so-Polarised.html">previous post</a> was whether code quality mattered to AI. I am now more convinced that it does. What I have observed in extended use is this: unless guided carefully, Claude produces more code than necessary, with weaker abstractions and noticeable duplication. As the codebase grows, the problem compounds. A bug fixed in one place introduces a bug somewhere else. Fix that, and you either recreate the original defect or produce a new one. It becomes a kind of Dr. Strange vs Dormammu time loop, where you are trapped in an endless cycle of regression; or, alternatively, a maddening game of whack-a-mole.</p>

<figure style="float: right; margin: 0 0 1em 2em; max-width: 400px;">
  <img src="/images/dormammu.png" alt="Dormammu Time Loop" style="width: 100%;" />
  <figcaption style="text-align: center;">Trapped in an endless cycle of regression</figcaption>
</figure>

<p>The pattern is not surprising. Claude is highly influenced by the existing codebase. If the surface area is large, inconsistent, or structurally weak, the model will amplify those characteristics. Conversely, if the surface area is small, cohesive and internally consistent, the model’s output improves markedly.</p>

<p>For clean code, three principles dominate.</p>

<p><strong>Strong Domain Models</strong><br />
The core concepts of the system should be explicit, named, and represented directly in code. Behaviour should live with the concepts it belongs to. When the model is coherent, both humans and AI can extend it predictably. When the domain is implicit or smeared across utilities and controllers, every change becomes guesswork.</p>

<p><strong>Encapsulation</strong><br />
Keep data and behaviour together and expose only meaningful operations that reflect the language of the domain. Do not provide mutators (setters) and avoid casual accessors (getters); every accessor that leaks state invites distributed behaviour, breaking the domain model. AI systems are particularly sensitive to porous boundaries, because they will happily reimplement logic.</p>

<p><strong>Minimal Conditional Logic</strong><br />
All but the briefest branching structures are a code smell. They signal decisions being made too late, missing domain concepts, missing polymorphism, or collapsed responsibilities. Nested conditionals increase cognitive load and expand the probability space the model must reason over. Move decisions back to the caller, which already knows the intent, or replace conditionals with richer, polymorphic domain types. This reduces complexity at the point of execution and keeps behaviour aligned with explicit intent rather than inferred state.</p>

<h2>When Claude got everything right</h2>

<p>That said, it would be misleading to suggest the experience is uniformly negative. Recently I built a small utility application for testing single sign on in a single prompt, and Claude produced exactly what I wanted. The prompt was:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Create a very simple web application for testing authentication with azure.
It should let me sign in, and when I click a button, makes a request to a 
backend service using the bearer token. The backend service is 
../azure-ad-jwt-debugger. Use the msal library as appropriate.
</code></pre></div></div>

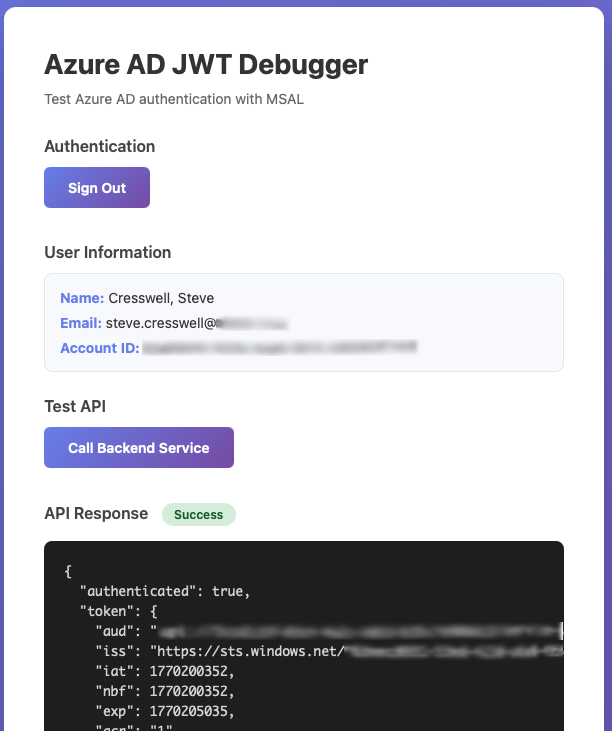
<p>And Claude delivered precisely that. Below is the generated interface…</p>

<figure style="text-align: center; margin: 2em 0;">
  <img src="/images/azure-ad-jwt-debugger.png" alt="Azure AD JWT Debugger" style="display: block; margin: 0 auto;" />
  <figcaption>The Azure AD JWT debugger interface, generated in a single prompt</figcaption>
</figure>

<p>It signs in with MSAL, retrieves the token, and calls the backend with the bearer token exactly as requested. Interestingly, it did not just implement the minimum described in the prompt. It also added:</p>

<ul>
  <li>A sign out button</li>
  <li>A structured JSON response display panel</li>
</ul>

<p>Neither of these were explicitly requested; both were appreciated. You can view the source code <a href="https://github.com/cressie176/azure-ad-jwt-debugger-web">here</a>. I have not reviewed it, since in this case, I do not envisage needing to modify it.</p>

<p>In conclusion, when the intent is crisp and the domain small, vibe coding may work extremely well. When the system grows and architectural trade-offs become material, discipline becomes essential. That is not an argument against generative AI. It is an argument for treating it as a powerful amplifier. Code quality matters more, not less, in the age of generative AI. Until models evolve in ways that reason more structurally about long-term design consequences, sustainable AI-assisted development depends on disciplined architecture. If the underlying design is coherent, it accelerates you. If it is messy, it accelerates the mess.</p>]]></content><author><name>Stephen Cresswell</name></author><category term="Generative AI" /><category term="Claude Code" /><category term="Clean Code" /><category term="Vibe Coding" /><summary type="html"><![CDATA[Further experience with Claude has strengthened my view that code quality matters more, not less, in the age of vibe coding. Left unguided, it amplifies duplication and weak abstractions; tightly constrained, it can be impressively precise. Generative AI is an amplifier. It accelerates coherence, and it accelerates mess.]]></summary></entry><entry><title type="html">Why Are Experiences Of Vibe Coding So Polarised?</title><link href="http://www.stephen-cresswell.com/2026/01/01/Why-Are-Experiences-Of-Vibe-Coding-So-Polarised.html" rel="alternate" type="text/html" title="Why Are Experiences Of Vibe Coding So Polarised?" /><published>2026-01-01T00:00:00+00:00</published><updated>2026-01-01T00:00:00+00:00</updated><id>http://www.stephen-cresswell.com/2026/01/01/Why-Are-Experiences-Of-Vibe-Coding-So-Polarised</id><content type="html" xml:base="http://www.stephen-cresswell.com/2026/01/01/Why-Are-Experiences-Of-Vibe-Coding-So-Polarised.html"><![CDATA[<h2 id="tldr">TL;DR</h2>
<p>This post explores why experiences with Generative AI assisted software development vary so dramatically. While some developers report order of magnitude productivity gains, others encounter architectural drift, excessive code, and serious operational risk. This gap is not primarily caused by the tools themselves, but by differences in goals, constraints, and methods of use.</p>

<p>Treating Generative AI as a meta tool that operates on intent rather than code mechanics, the post makes explicit its own optimisation goals: negligible operational debt and highly malleable, clean code. A controlled experiment using a small but realistic URL shortener service tests three ways of working with Claude Code.</p>

<p>True <a href="https://x.com/karpathy/status/1886192184808149383">vibe coding</a>, where you <em>“forget the code even exists”</em>, proved unreliable. A guided approach using techincal prompts, explicit implementation notes, rules, and manual review produced a clean, low debt system in just over an hour, delivering an estimated eight to sixteen times improvement over manual development. However, these gains should be interpreted cautiously, as coding represents only a fraction of a software engineer’s working time. In contrast, an unattended approach without guidance completed faster but generated substantially more code, significant technical and operational debt, and multiple design regressions.</p>

<p>The conclusion is that Generative AI can deliver dramatic gains, but only when projects are already established or properly bootstrapped, and the agent is strongly constrained. Left unattended, it reliably drifts towards verbosity and accidental complexity. The real question for organisations is therefore not whether to adopt Generative AI, but how to use it in a way that aligns with their long term engineering goals.</p>

<h2 id="introduction">Introduction</h2>
<p>Jason Gorman’s recent <a href="https://codemanship.wordpress.com/2025/11/25/the-future-of-software-development-is-software-developers/">post</a> on the future of software development is causing quite a stir. The comments on the accompanying Hacker News <a href="https://news.ycombinator.com/item?id=46424233">discussion</a> span an extraordinary range of experience with vibe coding, particularly when using Claude Code. Some describe dramatic productivity gains and rapid delivery of complex systems. Others report dangerously misleading output, architectural drift, and large amounts of unusable code. Both sides speak with confidence, often dismissing the other as naïve, reckless, or simply doing it wrong. The discussion reflects a broader pattern which has been bothering me for some time.</p>

<p>I have been a professional software engineer for thirty years, and strong disagreements are nothing new. Functional versus object oriented programming, static versus dynamic typing, competing approaches to testing. What is different this time is the nature of the tool itself. Generative AI does not primarily operate at the level of a language, framework, or architectural paradigm. It operates at the level of intent. You describe the outcome you want and it produces an implementation that attempts to achieve it. For straightforward applications, where the architectural trade offs are limited or inconsequential, this can be highly effective. However, once those trade offs become material, around performance, evolvability, correctness or operational risk, the model is still making implicit architectural decisions without properly accounting for their long term impact. It is improving quickly, but it is not yet a replacement for professional judgement.</p>

<p>It does not matter that Generative AI is unusually non-deterministic. For it to be useful to anyone, it still has to produce desired outcomes with sufficient consistency. That makes the scale and intensity of the reported disagreement surprising. Vastly different experiences are unlikely to be explained by an inherent defect in the tool itself. Allowing for <a href="https://thedecisionlab.com/biases">bias</a> and differing <a href="https://keirsey.com/temperament-overview/">personality temperaments</a> does not adequately explain the size of gap this time. The same tool is being described, with equal confidence, as producing dangerous, unmaintainable AI slop on the one hand, and delivering twenty times productivity on the other.</p>

<p>This gap is pushing organisations to make extreme decisions. Some, driven by unrealistic expectations, are rushing too quickly into AI adoption, creating unnecessary anxiety and disruption. Others are avoiding it entirely, missing out on potential benefits and frustrating their internal AI champions. The gap needs to be understood and closed.</p>

<h2 id="what-i-want-from-generative-ai">What I Want From Generative AI</h2>

<p>One possible explanation for difference in experience is that people want different outcomes. If that is the case, then disagreement about Generative AI performance is inevitable. Before comparing tools or techniques, the goals themselves need to be explicit. I want Generative AI to rapidly create applications with the following characteristics:</p>

<h3 id="1-negligible-operational-debt">1. Negligible Operational Debt</h3>
<p>Operational debt is distinct from technical debt. Technical debt only incurs a cost when change is required and is often an explicit trade-off. Operational debt creates ongoing risk and <a href="https://blog.while-true-do.io/devops-4-types-of-work/">unplanned work</a> and, in the worst cases, can consume an entire team’s capacity through incidents and urgent remediation.</p>

<h3 id="2-unparalleled-malleability">2. Unparalleled Malleability</h3>
<p><a href="https://www.oreilly.com/library/view/clean-code-a/9780136083238/">Clean Code</a> is malleable. When we write clean code, we make a comparatively small sacrifice now to reserve the ability to change rapidly in the future. The best way to achieve clean code is to write as little code as possible. This is done by creating a good domain model. When the domain model is good, the code vanishes. As Linus Torvalds is <a href="https://read.engineerscodex.com/p/good-programmers-worry-about-data">reported</a> to have said:</p>

<blockquote>
  <p>“Bad programmers worry about the code. Good programmers worry about data structures and their relationships.”</p>
</blockquote>

<p>A good domain model requires good encapsulation. Behaviour is contained in one place, colocated with the associated data. Accessors are few, mutators fewer still. Conditional logic is pushed to the boundaries of the application and eliminated internally through polymorphism. The code clearly expresses intent.</p>

<p>I have a nagging suspicion that my attachment to clean code may be what Scott Adams calls <a href="https://en.wikipedia.org/wiki/Loserthink">Loserthink</a>, and no longer needed in the world of Generative AI. Until that suspicion is proven, I am sticking with it though. The risk of a future filled with vast quantities of even less malleable code than we already have is too great.</p>

<h2 id="my-experience-of-vibe-coding-so-far">My Experience Of Vibe Coding (So Far)</h2>

<h3 id="the-good">The Good</h3>

<p>It is often stated that Generative AI is effective at mechanical or rote tasks, or comparable to the output of a junior engineer, but this is not where it offers the most value. The area where I have found my Generative AI tool of choice, <a href="https://www.claude.com/product/claude-code">Claude Code</a>, to be most effective is where I have strong high-level judgement about what needs to be achieved, but lack the detailed, low-level knowledge to implement it without time, research, and mistakes. In those cases, the limiting factor is not judgement, but execution.</p>

<p>CI/CD pipelines leveraging Docker provide a good example. I know what I want a pipeline to do, how the stages should fit together, and what correct behaviour looks like. Implementing that by hand usually involves reading documentation, iterating on syntax, and discovering edge cases through failure. Claude is much faster at cycling through that execution loop than I am, especially after installing the <a href="https://cli.github.com">GitHub CLI</a>, which is an absolute game changer for working with <a href="https://github.com/features/actions">GitHub Actions</a>!</p>

<p>In summary, Generative AI adds the most value when it operates below my level of judgement but above my knowledge or ability to acquire it. It accelerates low-level execution without being asked to make high-level decisions it is poorly suited to make.</p>

<h3 id="the-bad">The Bad</h3>

<p>At the same time, Claude, has ignored explicit instructions, made false assumptions, implemented changes that were not requested, and drifted away from the intended structure, particularly early in a codebase when there is less existing context. It has also misdiagnosed problems and disappeared down rabbit holes without ever fixing them, or worse, unilaterally decided that they can be safely ignored.</p>

<p>What stands out is how sensitive the results are to relatively small changes in how the tool is used. Claude is not a compiler. The results are not deterministic. Small differences in context, ordering, or phrasing can lead to materially different outcomes, even when the intent appears unchanged. Overall, the outcomes are still positive, but I have yet to achieve the 20x improvement reported by some. Either those reports are grossly overstated, or those making them have found ways to circumvent these issues and make Claude perform consistently well. If the latter is true, I want to learn and adopt their methods, but what are they?</p>

<h2 id="what-we-need-is-an-experiment">What We Need Is An Experiment</h2>

<p>To move this discussion forward, we need something more concrete than confident anecdote. When the same tool is reported to produce both dangerous, unmaintainable systems and dramatic productivity gains, opinion alone cannot tell us whether the difference lies in the tool itself, the goals being optimised for, or the way it is being used. The only way to separate those factors is to make the goals explicit and then test, in a controlled way, whether a particular method of using Generative AI can reliably produce outcomes aligned with them. What is needed is a repeatable test case against which different methods can be evaluated. It must be small enough to run repeatedly, representative of real world software, and sufficiently complex to expose meaningful trade offs and failure modes. A URL shortening service meets those criteria. Here are the stories:</p>

<table>
  <thead>
    <tr>
      <th>Story</th>
      <th>Title</th>
      <th>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><a href="https://github.com/cressie176/shorty/issues/1">EPIC</a></td>
      <td>URL Shortener Service</td>
      <td>Build a complete URL shortener service with persistence, automatic expiry, and scheduled maintenance.</td>
    </tr>
    <tr>
      <td><a href="https://github.com/cressie176/shorty/issues/2">1</a></td>
      <td>Project Initialisation</td>
      <td>Create the project structure and infrastructure.</td>
    </tr>
    <tr>
      <td><a href="https://github.com/cressie176/shorty/issues/3">2</a></td>
      <td>Shorten URL</td>
      <td>Shortens the given URL.</td>
    </tr>
    <tr>
      <td><a href="https://github.com/cressie176/shorty/issues/4">3</a></td>
      <td>Get URL</td>
      <td>Returns a URL for the given short key.</td>
    </tr>
    <tr>
      <td><a href="https://github.com/cressie176/shorty/issues/5">4</a></td>
      <td>URL Redirection</td>
      <td>Redirect requests for a short key to the URL.</td>
    </tr>
    <tr>
      <td><a href="https://github.com/cressie176/shorty/issues/6">5</a></td>
      <td>Improve Duplicate Key Handling</td>
      <td>Detect and handle the extremely rare case where the same short key is generated for different URLs.</td>
    </tr>
    <tr>
      <td><a href="https://github.com/cressie176/shorty/issues/7">6</a></td>
      <td>Expire Redirects</td>
      <td>Automatically expire the redirects when they have not been accessed for a configurable period of time.</td>
    </tr>
    <tr>
      <td><a href="https://github.com/cressie176/shorty/issues/8">7</a></td>
      <td>Delete Expired Redirects</td>
      <td>Automatically delete expired redirects.</td>
    </tr>
    <tr>
      <td><a href="https://github.com/cressie176/shorty/issues/9">8</a></td>
      <td>Schedule Database Maintenance</td>
      <td>Schedule daily database maintenance to maintain PostgreSQL query planner statistics.</td>
    </tr>
  </tbody>
</table>

<h3 id="hypothesis">Hypothesis</h3>

<p>The vast variation of experience comes from how Generative AI is being used, not from a fundamental weakness in the tool itself.</p>

<h3 id="apparatus">Apparatus</h3>

<ul>
  <li><strong>Machine:</strong> MacBook M1 Pro with 32GB RAM</li>
  <li><strong>Operating system:</strong> macOS 15.6.1 (24G90)</li>
  <li><strong>Model:</strong> Claude Sonnet 4.5 via AWS Bedrock</li>
  <li><strong>Context window:</strong> 1MB</li>
  <li><strong>Claude version:</strong> 2.0.76</li>
  <li><strong>Editor:</strong> <a href="https://zed.dev">zed</a> (barely used)</li>
  <li><strong>Generative AI execution:</strong> Separate terminal window running in plan mode, with safe GitHub and Bash commands pre-allowed</li>
  <li><strong>CLI tooling:</strong> <a href="https://cli.github.com">GitHub CLI</a> and other <a href="https://github.com/cressie176/cressie176-claude-marketplace/blob/main/plugins/macos-tools/commands/install-macos-tools.md">macos-tools</a></li>
  <li><strong>Claude Marketplace</strong>: <a href="https://github.com/cressie176/cressie176-claude-marketplace">cressie176-claude-marketplace</a></li>
  <li><strong>Node.js Templates:</strong> <a href="https://github.com/cressie176/node-templates">node-templates</a></li>
  <li><strong>Stories:</strong> <a href="https://github.com/cressie176/shorty/issues">shorty/issues</a></li>
</ul>

<h3 id="method-1-prompt-bootstrapping-implementation-notes-and-manual-accepts-abandoned">Method 1: Prompt Bootstrapping, Implementation Notes and Manual Accepts (Abandoned)</h3>
<p>The initial approach was to use pre-written stories, marketplace skills and interactive prompts to fully implement the URL Shortening service. The intention was to encode structure, constraints, and best practices entirely through instructions. Unfortunately, this proved unreliable, particularly while the codebase was in infancy. Even when instructions were repeated and made increasingly explicit, Claude would occasionally ignore them or drift away from the intended structure. Continuing in this direction wasted both time and tokens. I needed a way to bootstrap the application without Claude.</p>

<h3 id="method-2-template-bootstrapping-implementation-notes-and-manual-accepts">Method 2: Template Bootstrapping, Implementation Notes and Manual Accepts</h3>
<p>For my second attempt, I still worked from pre-written stories, marketplace skills and interactive prompts, but my infrastructure story instructed Claude to bootstrap the service from a custom <a href="https://docs.github.com/en/repositories/creating-and-managing-repositories/creating-a-template-repository">GitHub template repository</a>. A base service template establishes the core structure, with additional templates layered on top for concerns such as PostgreSQL or other infrastructure. This allows common practices to be shared while still supporting different combinations.</p>

<p>Traditional automation struggles here. As the number of layers increases, reliably merging templates becomes difficult, particularly where cross-cutting concerns are involved. This is where Generative AI proved useful. Each layer includes a “Wiring.md” file describing how it should be integrated into the base. Claude can read and apply these instructions in a way that would be awkward to achieve with scripts. The bootstrap process also made it possible to provide Claude.md files in the templates, but this introduced merge problems as templates were combined. Using <a href="https://code.claude.com/docs/en/memory">rules</a> proved more effective, as each template can include its own rules separately.</p>

<p>Even with templates and rules in place, Generative AI still required technical direction at the story level. Each story therefore includes explicit Implementation Notes recommending an approach, along with reminders to review the relevant rules and skills. These could have been entered interactively, but this would have made the experiment less repeatable and less transparent. Templates capture structural decisions, rules capture behavioural constraints, and stories capture local trade-offs and more nuanced technical decisions. Together, they allow experience to be shared through the artefact itself, rather than through constant explanation or review.</p>

<p>Claude was instructed to install the required templates before implementing any functional stories. With that foundation in place, apart from the occasional and minor course correction, a single prompt was all that was required.</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>╭─── Claude Code v2.0.76 ────────────────────────────────────────────────────────────────────────────╮
│                                                    │ Tips for getting started                      │
│                    Welcome back!                   │ Run /init to create a CLAUDE.md file          │
│                                                    │ ──────────────────────────────────────────────│
│                    * ▗ ▗   ▖ ▖ *                   │ Recent activity                               │
│                   *             *                  │ No recent activity                            │
│                    *   ▘▘ ▝▝   *                   │                                               │
│                                                    │                                               │
│ arn:aws:bedrock:eu-west-1:808… · API Usage Billing │                                               │
│          ~/Development/cressie176/shorty           │                                               │
╰────────────────────────────────────────────────────────────────────────────────────────────────────╯

  /model to try Opus 4.5. Note: you may need to request access from your cloud provider

──────────────────────────────────────────────────────────────────────────────────────────────────────
&gt; Implement the URL Shortener epic https://github.com/cressie176/shorty/issues/1 one story at a time 
──────────────────────────────────────────────────────────────────────────────────────────────────────
  ? for shortcuts
</code></pre></div></div>
<p>One deliberate adjustment was made around test-driven development. I allowed Claude to generate tests and production code for a story in a single pass, rather than enforcing a strict red, green, refactor cycle. My assumption was that the model does not benefit from incremental test feedback in the same way a human does, although this remains an open question.</p>

<p>Almost all of my interaction during this phase took place using Claude via the terminal. I reviewed diffs and observed Claude’s workflow there, intervening only when necessary. I didn’t avoid editing in an IDE, I just never felt the need. I only switched to zed once Claude had completed each story, in order to review the changes as a coherent logical unit and to scan through the tests.</p>

<p>I reran the experiment multiple times from the same starting point and received approximately similar results.</p>

<h3 id="results">Results</h3>

<p>The code can be found here: <a href="https://github.com/cressie176/shorty/">shorty</a></p>

<table>
  <thead>
    <tr>
      <th>Story</th>
      <th>Description</th>
      <th>Status</th>
      <th>Time</th>
      <th>Interventions</th>
      <th>Commit</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>1</td>
      <td>Project Initialisation</td>
      <td>✅</td>
      <td>00:08</td>
      <td>0</td>
      <td><a href="https://github.com/cressie176/shorty/commit/2f37d746d84039a2f58e239fa5bae90760db194b">2f37d74</a></td>
    </tr>
    <tr>
      <td>2</td>
      <td>Shorten URL</td>
      <td>✅</td>
      <td>00:21</td>
      <td>7</td>
      <td><a href="https://github.com/cressie176/shorty/commit/2f37d746d84039a2f58e239fa5bae90760db194b">b83c51f</a></td>
    </tr>
    <tr>
      <td>3</td>
      <td>Get URL</td>
      <td>✅</td>
      <td>00:10</td>
      <td>4</td>
      <td><a href="https://github.com/cressie176/shorty/commit/ea2f83796b255a7c1130ae4baa92ac097deba1e0">ea2f837</a></td>
    </tr>
    <tr>
      <td>4</td>
      <td>URL Redirection</td>
      <td>✅</td>
      <td>00:07</td>
      <td>3</td>
      <td><a href="https://github.com/cressie176/shorty/commit/9ebc8e37754125c7f6d5feb7c464643a1d24e232">9ebc8e3</a></td>
    </tr>
    <tr>
      <td>5</td>
      <td>Handle Key Collisions</td>
      <td>✅</td>
      <td>00:10</td>
      <td>3</td>
      <td><a href="https://github.com/cressie176/shorty/commit/9da1d50236d8eae8bd378246d7acd14294859d22">9da1d50</a></td>
    </tr>
    <tr>
      <td>6</td>
      <td>Expire Redirects</td>
      <td>✅</td>
      <td>00:06</td>
      <td>0</td>
      <td><a href="https://github.com/cressie176/shorty/commit/aafa1ba1d980758b303e2749df01f711e73f69eb">aafa1ba</a></td>
    </tr>
    <tr>
      <td>7</td>
      <td>Delete Expired Redirects</td>
      <td>✅</td>
      <td>00:03</td>
      <td>0</td>
      <td><a href="https://github.com/cressie176/shorty/commit/64199839424353f7bd002400afbb28631326607d">6419983</a></td>
    </tr>
    <tr>
      <td>8</td>
      <td>Schedule Database Maintenance</td>
      <td>✅</td>
      <td>00:02</td>
      <td>0</td>
      <td><a href="https://github.com/cressie176/shorty/commit/4ed283719e72528998c7d6cccf3ffdafffae5339">4ed2837</a></td>
    </tr>
    <tr>
      <td> </td>
      <td> </td>
      <td> </td>
      <td>01:07</td>
      <td>17</td>
      <td> </td>
    </tr>
  </tbody>
</table>

<h4 id="tool-rejections-deduped">Tool Rejections (deduped)</h4>
<ol>
  <li>Don’t duplicate config in tests</li>
  <li>Prefer single-line if statements</li>
  <li>Don’t use try-catch for testing errors, use throws/rejects</li>
  <li>Pass the full redirect config not just the key</li>
  <li>Use object parameters in constructors</li>
  <li>Don’t be lazy with assertions (use eq not ok/match when you know the full string)</li>
  <li>Inject the full error message into the JSX template</li>
  <li>Suppress expected error logs in tests</li>
  <li>Destructure { rows } instead of result.rows</li>
</ol>

<p>Using this approach, Claude correctly implemented the URL shortener service in one hour and seven minutes, with minimal intervention or further prompting. The architectural drift and disobedience seen earlier largely disappeared once the environment was properly bootstrapped.</p>

<p>There were some minor style problems. Claude is overly fond of blank lines, and despite it being mentioned in the implementation plan, it missed that an object’s toJSON() method will be called automatically by Hono’s JSON serialiser. Slightly more serious was that Claude omitted running database migrations from each integration test. The tests still passed because migrations were run from the template Postgres.test.ts, but this may not have run first, potentially causing intermittent failures. I have since updated the node-pg template to run migrations automatically from within the Postgres class to avoid this in future. Overall, these are minor niggles, and the code satisfied my goals of minimal operational debt and cleanliness.</p>

<p>I estimate it would have taken me 1 to 2 working days to produce an equivalent codebase from the same templates without AI. This would suggest that Claude achieved an 8x to 16x improvement. However, the implementation time does not reflect the full cost. These results required repeated iteration on both the stories and the skills. Significant effort went into refining story structure, clarifying implementation notes, and adjusting skills so that Claude behaved consistently.</p>

<h3 id="method-3-templated-bootstraping-no-implementation-notes-and-automatic-accepts">Method 3: Templated Bootstraping, No Implementation Notes and Automatic Accepts</h3>

<p>As another experiment, I tried a deliberately unattended approach without the benefit of implementation notes. The code can be found here: <a href="https://github.com/cressie176/shorty/tree/claude-unattended">claude-unattended</a>
<br /></p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>╭─── Claude Code v2.0.76 ────────────────────────────────────────────────────────────────────────────╮
│                                                    │ Tips for getting started                      │
│                    Welcome back!                   │ Run /init to create a CLAUDE.md file          │
│                                                    │ ──────────────────────────────────────────────│
│                    * ▗ ▗   ▖ ▖ *                   │ Recent activity                               │
│                   *             *                  │ No recent activity                            │
│                    *   ▘▘ ▝▝   *                   │                                               │
│                                                    │                                               │
│ arn:aws:bedrock:eu-west-1:808… · API Usage Billing │                                               │
│          ~/Development/cressie176/shorty           │                                               │
╰────────────────────────────────────────────────────────────────────────────────────────────────────╯

  /model to try Opus 4.5. Note: you may need to request access from your cloud provider

──────────────────────────────────────────────────────────────────────────────────────────────────────
&gt; I want you to implement https://github.com/cressie176/shorty/issues/1 story by story.
  I want you to completely ignore the implementation notes within the GitHub issues for everyting
  EXCEPT the Project Initialisation story. You MUST NOT even read them otherwise they will influence 
  you. To avoid reading them pipe the output from the gh issue command into something to remove 
  everything after the "Implementation Notes" title so that it is completely unavailable to you. 
  When you think a story is done, build, lint, test and commit.
──────────────────────────────────────────────────────────────────────────────────────────────────────
  ? for shortcuts
</code></pre></div></div>

<h3 id="results-1">Results</h3>

<p>Claude completed all eight stories in 30 minutes and 34 seconds. On the surface, this looks impressive. In reality the code was a hot mess.
<br />
<br /></p>

<table>
  <thead>
    <tr>
      <th>Area</th>
      <th>Metric</th>
      <th>Method 2 (Guided)</th>
      <th>Method 3 (Unattended)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Domain</td>
      <td>Files</td>
      <td>1</td>
      <td>1</td>
    </tr>
    <tr>
      <td> </td>
      <td>TypeScript lines</td>
      <td>55</td>
      <td>6</td>
    </tr>
    <tr>
      <td> </td>
      <td>SQL lines</td>
      <td>0</td>
      <td>0</td>
    </tr>
    <tr>
      <td> </td>
      <td>TSX lines</td>
      <td>0</td>
      <td>0</td>
    </tr>
    <tr>
      <td> </td>
      <td>Comments</td>
      <td>0</td>
      <td>0</td>
    </tr>
    <tr>
      <td>Services</td>
      <td>Files</td>
      <td>4</td>
      <td>4</td>
    </tr>
    <tr>
      <td> </td>
      <td>TypeScript lines</td>
      <td>47</td>
      <td>199</td>
    </tr>
    <tr>
      <td> </td>
      <td>SQL lines</td>
      <td>7</td>
      <td>0</td>
    </tr>
    <tr>
      <td> </td>
      <td>TSX lines</td>
      <td>0</td>
      <td>0</td>
    </tr>
    <tr>
      <td> </td>
      <td>Comments</td>
      <td>0</td>
      <td>7</td>
    </tr>
    <tr>
      <td>Routes</td>
      <td>Files</td>
      <td>3</td>
      <td>3</td>
    </tr>
    <tr>
      <td> </td>
      <td>TypeScript lines</td>
      <td>31</td>
      <td>66</td>
    </tr>
    <tr>
      <td> </td>
      <td>TSX lines</td>
      <td>18</td>
      <td>0</td>
    </tr>
    <tr>
      <td> </td>
      <td>SQL lines</td>
      <td>0</td>
      <td>0</td>
    </tr>
    <tr>
      <td> </td>
      <td>Comments</td>
      <td>0</td>
      <td>0</td>
    </tr>
    <tr>
      <td>Overall</td>
      <td>Total files</td>
      <td>8</td>
      <td>8</td>
    </tr>
    <tr>
      <td> </td>
      <td>Total comments</td>
      <td>0</td>
      <td>7</td>
    </tr>
    <tr>
      <td> </td>
      <td><strong>Total lines (excl blanks)</strong></td>
      <td><strong>158</strong></td>
      <td><strong>271</strong></td>
    </tr>
  </tbody>
</table>

<p>The guided version produced 158 lines of code with no comments. The unattended version produced 271 lines with seven (pointless) comments. <strong>That’s 72% more code and 104% more TypeScript for the same behaviour!</strong></p>

<p>Furthermore, the unattended implementation introduced substantial technical and operational debt:</p>

<ul>
  <li>Unnecesary new services for key generation and expiry management.</li>
  <li>Redirects retrieved from the API were not expired.</li>
  <li>Consecutive database queries were performed using separate client calls, so they were not part of the same transaction, in disregard of the <a href="https://github.com/cressie176/cressie176-claude-marketplace/blob/main/plugins/typescript-service-cookbook/skills/typescript-service-cookbook/SKILL.md#unit-of-work-pattern-with-asynclocalstorage">Unit of Work</a> pattern.</li>
  <li>Errors polluted the logs during test runs in disregard of the <a href="https://github.com/cressie176/cressie176-claude-marketplace/blob/main/plugins/typescript-tdd-cookbook/skills/typescript-tdd-cookbook/SKILL.md#suppressing-expected-error-logs">Suppress Expected Error in Logs</a> guidance.</li>
  <li>It implemented an explicit rude word filter rather than removing vowels, increasing maintenance burden.</li>
  <li>setInterval was used for the maintenance tasks without unref(), which can prevent the process from exiting and does not scale horizontally.</li>
  <li>Functions were far larger, with SQL and JSX inlined making the code harder to follow, in disregard of the <a href="https://github.com/cressie176/cressie176-claude-marketplace/blob/main/plugins/typescript-clean-code-cookbook/skills/typescript-clean-code-cookbook/SKILL.md#function-design">Function Design</a> guidance.</li>
  <li>PostgreSQL was used poorly, with application code compensating for weak queries, e.g.
    <ul>
      <li>Expiry logic was checked in application code rather than expressed directly in a query.</li>
      <li>Duplicate urls were inserted rather than being upserted.</li>
      <li>Scheduling was done in application code in disgregard of the <a href="https://github.com/cressie176/cressie176-claude-marketplace/blob/main/plugins/postgresql-cookbook/skills/postgresql-cookbook/SKILL.md#scheduled-deletion-of-old-records-with-pg_cron">pg_cron</a> guidance.</li>
    </ul>
  </li>
  <li>The codebase was littered with low value comments that narrated rather than clarified, in disregard of the <a href="https://github.com/cressie176/cressie176-claude-marketplace/blob/main/plugins/typescript-clean-code-cookbook/skills/typescript-clean-code-cookbook/SKILL.md#comments">Comments</a> guidance.</li>
  <li>Tests used Monkey patching instead of dependency injection to fake behaviour.</li>
  <li>Fetch was used in tests directly increasing duplication, reducing readability, making them brittle. and in disregard of the <a href="https://github.com/cressie176/cressie176-claude-marketplace/blob/main/plugins/typescript-tdd-cookbook/skills/typescript-tdd-cookbook/SKILL.md#test-client-pattern">Test Client</a> pattern.</li>
</ul>

<h2 id="conclusion">Conclusion</h2>

<p><strong>Method 1 (Prompt Bootstrapping, Implementation Notes, and Manual Accepts)</strong> showed that Claude is ineffective when asked to bootstrap a non-trivial system from scratch using prompts alone. Even with detailed stories and marketplace skills, progress was slow and fragile, with frequent drift making the process an uphill and unnecessary battle. The results suggest that Claude is far more productive when working on an existing or bootstrapped codebase, and that it appears to weight existing artefacts more heavily than abstract guidance from prompts or skills. This limitation motivated the move to a templated bootstrap approach.</p>

<p><strong>Method 2 (Template Bootstrapping, Implementation Notes, and Manual Accepts)</strong> demonstrates that Claude can produce high-quality code far more rapidly than even an experienced software engineer, but only when projects are already established or properly bootstrapped, and the agent is guided by effective prompts, whether through marketplace skils, embedded directly in user stories or provided interactively. While marketplace skills represent a long-term investment that can be reused, stories do not. Incorporating detailed implementation notes into each story was necessary for this experiment, but it also made those stories brittle. Real world success will therefore depend either on becoming very good at writing implementation notes up front, or on the engineers driving Claude being skilled enough to provide sufficiently strong just-in-time guidance. Where that is the case, stories that previously took days can be delivered in hours, shifting the primary bottleneck from implementation to story writing. It may be that AI-empowered teams will need to be significantly smaller, narrower in focus, and able to move rapidly between applications and domains to circumvent this bottleneck.</p>

<p>It is also important to put these productivity gains into context. Software engineers do not spend anything close to 100% of their time writing code. Design discussions, team ceremonies, research, troubleshooting, supporting others, administrative work, and training all consume significant portions of a typical working day. Even a dramatic improvement in coding effectiveness therefore does not translate directly into an equivalent improvement in overall productivity.</p>

<p>In contrast, <strong>Method 3 (Template Bootstrapping, No Implementation Notes, and Automatic Accepts)</strong> demonstrates that Claude is not yet something that can be left to operate unattended while still producing consistently good outcomes. Without strong constraints, it reliably drifts towards verbosity, duplication, and accidental complexity, even when the resulting system is functionally correct. That gap between apparent success and long-term maintainability likely explains much of the current scepticism and pushback.</p>

<p>After all of this, I am still left pondering the following open questions:</p>

<ol>
  <li>Were my goals the right ones (particularly my need for Clean Code)?</li>
  <li>Was my method the most effective way to use Generative AI, and specifically Claude Code?</li>
  <li>Do other goals matter more in different contexts?</li>
</ol>

<p>If you are getting better results from vibe coding, what are you optimising for, and how does your approach support that? If you are getting poor results how does your approach differ from mine? I’d love to know.</p>]]></content><author><name>Stephen Cresswell</name></author><category term="Generative AI" /><category term="Claude Code" /><category term="Clean Code" /><category term="Vibe Coding" /><summary type="html"><![CDATA[A controlled experiment reveals why developers report vastly different experiences with AI coding tools - and what it takes to achieve reliable, high-quality results.]]></summary></entry><entry><title type="html">Addendum: Open Source Contributions in Hiring</title><link href="http://www.stephen-cresswell.com/2025/01/21/addendum-open-source-contributions-in-hiring.html" rel="alternate" type="text/html" title="Addendum: Open Source Contributions in Hiring" /><published>2025-01-21T00:00:00+00:00</published><updated>2025-01-21T00:00:00+00:00</updated><id>http://www.stephen-cresswell.com/2025/01/21/addendum-open-source-contributions-in-hiring</id><content type="html" xml:base="http://www.stephen-cresswell.com/2025/01/21/addendum-open-source-contributions-in-hiring.html"><![CDATA[<p>After publishing my recent <a href="https://www.stephen-cresswell.com/2025/01/07/in-defence-of-coding-tests.html">article</a> defending coding tests, I read a <a href="https://www.linkedin.com/posts/james-mahy_stop-using-github-contributions-in-hiring-activity-7280527334883962880-esvT">post</a> by James Mahy, a genuinely kind, and exceptionally talented developer whom I ironically had the good fortune to interview some years ago. In it, he raises some interesting points, suggesting that GitHub contributions do not always reflect motivation, skill, or tenacity, and may even be misleading. My own experience leads me to a different conclusion.</p>

<p>I have been contributing to open source for almost two decades. It has taught me a great deal about real-world problem-solving, communication, and collaboration. Furthermore, reviewing a candidate’s contributions - whether personal projects, pull requests, or issues, can reveal insights into their creativity, communication skills, and technical mindset. This applies equally to junior developers because even small projects or issues can demonstrate qualities like passion, curiosity, intelligence, diligence, empathy, humility, and respect.</p>

<p>That said, I agree with James that open source contributions should not be a requirement. Plenty of excellent developers do not engage in open source for various reasons. But if someone has made meaningful contributions, I want to hear about them. For me, it is less about the green squares and more about the stories behind them; what interests they have, what challenges they faced, and what they learned along the way.</p>

<p>Open source is just one piece of the puzzle, but it is often a fascinating one. I believe it can be a valuable part of the hiring conversation, no matter what the candidate’s level of experience.</p>]]></content><author><name>Stephen Cresswell</name></author><category term="Software Engineering" /><category term="Hiring" /><category term="Interviews" /><category term="Coding Tests" /><category term="Open Source" /><summary type="html"><![CDATA[Why open source contributions can reveal valuable insights about candidates - not as a requirement, but as a window into passion, problem-solving, and communication skills.]]></summary></entry><entry><title type="html">In Defence Of Coding Tests</title><link href="http://www.stephen-cresswell.com/2025/01/07/in-defence-of-coding-tests.html" rel="alternate" type="text/html" title="In Defence Of Coding Tests" /><published>2025-01-07T00:00:00+00:00</published><updated>2025-01-07T00:00:00+00:00</updated><id>http://www.stephen-cresswell.com/2025/01/07/in-defence-of-coding-tests</id><content type="html" xml:base="http://www.stephen-cresswell.com/2025/01/07/in-defence-of-coding-tests.html"><![CDATA[<p>Hiring software engineers is one of the most challenging and critical responsibilities for any team. Having founded a consultancy and led hiring for other companies, I know first-hand how much is at stake.</p>

<p>A wrong hire can delay work, frustrate teams, and cost both significant time and money. It is not good for the candidate either. Being in the wrong role causes anxiety, damages confidence, and leaves a blemish on their career history. Furthermore, dealing with someone who underperforms is disruptive, demoralising and exhausting for their manager, their colleagues, and the person themselves. Conversely, a good hiring process means that successful candidates get to work on interesting projects with great colleagues and vice versa. This is why it is in everyone’s interest that the process is effective.</p>

<p>However, the methods used in hiring have faced increasing scrutiny, particularly coding tests, whether take-home or live. While these methods are not perfect, dismissing them outright risks missing valuable insights. Let me explore some of these debates and how thoughtful hiring processes can strike a balance.</p>

<h3 id="common-criticisms-of-coding-tests">Common Criticisms of Coding Tests</h3>

<p>Common criticisms of coding tests include:</p>

<ul>
  <li>
    <p><strong>Anxiety:</strong> Many candidates experience stress caused by live coding exercises, which can lead to underperformance during interviews.</p>
  </li>
  <li>
    <p><strong>Time constraints:</strong> Take-home projects can be burdensome, especially for those with limited time due to family or other commitments. An ex-colleague even refused to interview for companies who set take-home tests.</p>
  </li>
  <li>
    <p><strong>Unrealistic tests:</strong> Many coding tests focus on niche skills like recursion or bit masking that are rarely used in day-to-day work. These tests often fail to measure a candidate’s ability to perform in real-world scenarios, leaving a gap in assessing their practical effectiveness.</p>
  </li>
</ul>

<h3 id="why-a-live-coding-test-is-valuable">Why a Live Coding Test Is Valuable</h3>

<p>One of the most revealing parts of a coding interview is observing candidates using their toolchain (computer, IDE, command line, etc). An experienced software engineer develops a kind of muscle memory, navigating their environment with ease and efficiency. Whether it is memorised shortcuts, efficient workflows, favourite packages, or thoughtful organisation, these details strongly correlate with hands-on experience. They demonstrate not only a candidate’s technical skill but also their approach to problem-solving and familiarity with their craft. It is not about perfection; it is about the habits and fluency that only come from practice.</p>

<p>A live coding test allows me to observe these behaviours in action. It shows how candidates approach a problem, how they structure their code, and how they troubleshoot unexpected issues. It also provides insight into their communication skills and how they handle feedback, both of which are critical in collaborative environments.</p>

<p>In some cases, it can reveal red flags about a candidate. For instance, I have encountered several candidates who ignored feedback, which raised concerns about their adaptability and willingness to engage constructively. In another example, I asked a candidate to adapt their in-memory solution to one using persistence with a datastore of their choice. To my surprise, they responded with exasperation, raising serious concerns about their suitability for a collaborative, team-oriented culture.</p>

<h3 id="coding-tests-a-flexible-approach">Coding Tests: A Flexible Approach</h3>

<p>My preferred approach addresses the concerns around live and take-home tests by offering flexibility. I use tests that do not require company domain knowledge but do demonstrate frequently used software engineering skills. These tests are tailored to the experience level of the role, ensuring they are both relevant and fair. Candidates are encouraged to use whatever resources they have available, including Google, Stack Overflow, and AI tools. I always attempt the test myself to ensure its appropriateness and feasibility. Additionally, at least one existing employee of the appropriate level is asked to attempt it as well. I also try to put the candidate at ease prior to starting the live aspect of the test, rather than jumping straight in and advising them that it is not necessary to finish.</p>

<p>I provide candidates with the coding test beforehand. At a minimum, I ask them to read the exercise and come prepared with their environment ready to go. If they prefer, they can complete the test in advance and walk through their solution during the interview, although I will ask them to make changes so I can observe them work. This allows:</p>

<ul>
  <li>
    <p>Time-poor candidates to do the minimum and focus on live problem-solving,</p>
  </li>
  <li>
    <p>Candidates who feel anxious to prepare more thoroughly in advance.</p>
  </li>
</ul>

<p>This approach gives candidates control over how they prepare and ensures I can still evaluate problem-solving skills, adaptability, and hands-on coding ability. Additionally, I have offered a second chance to candidates who suffered badly due to nerves but who performed well otherwise.</p>

<h3 id="final-thoughts">Final Thoughts</h3>

<p>To paraphrase Warren Buffett, at the heart of any good hiring process is the search for intelligence, energy, and integrity. Depending on the level of role, knowledge and wisdom become increasingly important too. No hiring process will ever be perfect at evaluating these criteria, but thoughtful adjustments, like offering flexible coding tests, observing how candidates use their tools can make the process more effective. The goal is to use these tools not as rigid gatekeepers but as opportunities to learn about candidates and identify those who will thrive in your team.</p>

<h3 id="recommended-reading">Recommended Reading</h3>
<ul>
  <li><a href="https://blog.codinghorror.com/why-cant-programmers-program/">Why Can’t Programmers.. Program?</a></li>
  <li><a href="https://dannorth.net/interviewing-for-evidence/">Interviewing for Evidence</a></li>
</ul>]]></content><author><name>Stephen Cresswell</name></author><category term="Software Engineering" /><category term="Hiring" /><category term="Interviews" /><category term="Coding Tests" /><summary type="html"><![CDATA[Why live coding tests remain valuable in hiring, and how to make them fair and effective for both candidates and employers.]]></summary></entry><entry><title type="html">Introducing Filby: An Open Source Library for Managing Shared Reference Data</title><link href="http://www.stephen-cresswell.com/2024/12/29/introducing-filby.html" rel="alternate" type="text/html" title="Introducing Filby: An Open Source Library for Managing Shared Reference Data" /><published>2024-12-29T00:00:00+00:00</published><updated>2024-12-29T00:00:00+00:00</updated><id>http://www.stephen-cresswell.com/2024/12/29/introducing-filby</id><content type="html" xml:base="http://www.stephen-cresswell.com/2024/12/29/introducing-filby.html"><![CDATA[<p>Shared reference data can be a tricky aspect of software development, especially in distributed or microservice-based architectures. Enter <strong>Filby</strong>, an open-source library that simplifies the management of such data, ensuring consistency, reliability, and flexibility. Here, we’ll explore how Filby works, its key benefits, and why it might be the solution you’ve been searching for.</p>

<h4 id="the-problem-managing-shared-reference-data">The Problem: Managing Shared Reference Data</h4>

<p>Most applications rely on reference data—information that changes infrequently but must remain consistent across the system. However, managing this data across distributed systems introduces challenges:</p>

<table>
  <thead>
    <tr>
      <th>Challenge</th>
      <th>Notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Consistency</td>
      <td>Whenever we duplicate our reference data, we increase the likelihood of inconsistency. Even if we have one authoritive source of truth, we may cache the reference data in multiple systems, resulting in temporary inconsisenty unless cache updates are sychronised. Given the reference data is slow moving, a short period of inconsistency may be acceptable.</td>
    </tr>
    <tr>
      <td>Load Times</td>
      <td>Some reference data sets may be too large to desirably load over a network connection for web and mobile applications. Therefore we should discourage accidentally including large data sets into a client bundle, or requesting large data sets over a network.</td>
    </tr>
    <tr>
      <td>Reliability</td>
      <td>Requesting data sets over a network may fail, especially when mobile. Bundling local copies of reference data into the application (providing they are not too large) will aleviate this, but increase the potential for stale data.</td>
    </tr>
    <tr>
      <td>Stale Data</td>
      <td>Even though reference data is slow moving, it will still change occasionally. Therefore we need a strategy for refreshing reference data.</td>
    </tr>
    <tr>
      <td>Temporality</td>
      <td>When reference data changes, the previous values may still be required for historic comparisons. Therefore all reference data should have an effective date. Effective dates can also be used to synchronise updates by including future records when the values are known in advance. This comes at the cost of increased size, and there may still be some inconsistency due to clock drift and cache expiry times.</td>
    </tr>
    <tr>
      <td>Evolution</td>
      <td>Both reference data, and our understanding of the application domain evolves over time. We will at some point need to make backwards incompatible changes to our reference data, and will need to do so without breaking client applications. This suggests a versioning and validation mechanism. The issue of temporality compounds the challenge of evolution, since we may need to retrospecively add data to historic records. In some cases this data will not be known.</td>
    </tr>
    <tr>
      <td>Local Testing</td>
      <td>Applications may be tested locally, and therefore any solution sould work well on a local development machine.</td>
    </tr>
  </tbody>
</table>

<h4 id="meet-filby-version-control-for-reference-data">Meet Filby: Version Control for Reference Data</h4>

<p>Think of Filby as <strong>version control for reference data</strong>. Just as source control systems like Git track changes to source code, Filby manages reference data changes. Like checking out a commit, your applications can use Filby to retrieve reference data for a given change set id. They can also inspect the changelog to find which change set was in effect at a given point in time, and subscribe to reference data update notifications.</p>

<h4 id="key-features-and-benefits">Key Features and Benefits</h4>

<p>Filby offers a structured approach to managing shared, temporal reference data, delivering several advantages:</p>

<ol>
  <li><strong>Safe, Predictable Updates</strong>: Deploy new reference data ahead of time and activate it when needed.</li>
  <li><strong>Consistency Across Systems</strong>: The change set mechanism ensures consistency, even with distributed systems.</li>
  <li><strong>Historic and Future Data Access</strong>: Retrieve past data or schedule future changes.</li>
  <li><strong>Customisable Projections</strong>: Tailor views of reference data for specific clients or systems.</li>
  <li><strong>Version Control</strong>: Support backward-incompatible changes with versioned projections.</li>
  <li><strong>Caching Made Easy</strong>: Change sets should never change making them highly cacheable.</li>
  <li><strong>Local Development Support</strong>: Test applications locally using HTTP mocking libraries.</li>
</ol>

<h4 id="filbys-core-concepts">Filby’s Core Concepts</h4>

<p>To understand how Filby works, let’s break down its main components:</p>

<ul>
  <li><strong>Projections</strong>: Versioned views of reference data, tailored to specific use cases.</li>
  <li><strong>Entities</strong>: The individual pieces of reference data.</li>
  <li><strong>Data Frames</strong>: Snapshots of entities at specific points in time, grouped by change sets.</li>
  <li><strong>Change Sets</strong>: Logical bundles of updates with a common effective date.</li>
  <li><strong>Notifications</strong>: Update events for maintaining synced data across systems.</li>
  <li><strong>Hooks</strong>: Custom event handlers triggered by data changes.</li>
</ul>

<pre>
┌───────────────┐
│               │
│               │ announces changes via
│  Projection   │────────────────────────┐
│               │                        │
│               │                        │
└───────────────┘                        │
        │ depends on                     │
        │                                │
        │                                │
        │                                │
       ╱│╲                              ╱│╲
┌───────────────┐                ┌───────────────┐                 ┌──────────────┐
│               │                │               │                 │              │
│               │                │               │╲ delivered via  │              │
│    Entity     │                │ Notification  │─────────────────│     Hook     │
│               │                │               │╱                │              │
│               │                │               │                 │              │
└───────────────┘                └───────────────┘                 └──────────────┘
        │ aggregates                    ╲│╱ is raised by
        │                                │
        │                                │
        │                                │
       ╱│╲                               │
┌───────────────┐                ┌───────────────┐
│               │                │               │
│               │╲ is grouped by │               │
│  Data Frame   │────────────────│  Change Set   │
│               │╱               │               │
│               │                │               │
└───────────────┘                └───────────────┘
</pre>

<h4 id="a-real-world-use-case">A Real-World Use Case</h4>

<p>Imagine a system managing holiday park data. With Filby:</p>

<ol>
  <li>Define entities like “Park” and “Season” in JSON or YAML files.</li>
  <li>Create a changelog for the Park and Season data updates in JSON, YAML, CSV or SQL.</li>
  <li>Tailor projections to specific needs, such as a Mobile App requiring a compact view of park details.</li>
  <li>Use Filby’s API to retrieve park data at any point in time.</li>
  <li>Add “hooks” to notify other systems that new data and/or projects are available.</li>
</ol>

<pre>
               Change
               Hook       Invalidate Cache
           ┌─────────┐   ┌──────────────┐
           │         │   │              │
           │         ▼   │              ▼
┌────┬───────────┬──────────┐       ┌────────┐   GET /changelog/parks/v1        ┌──────────┐
│    │           │          │◀──────│        │◀─────────────────────────────────│          │
│    │           │ RESTful  │       │        │                                  │  Mobile  │
│ DB │   Filby   │   API    │       │  CDN   │                                  │   App    │
│    │           │          │       │        │   GET /projection/parks/v1?id=29 │          │
│    │           │          │◀──────│        │◀─────────────────────────────────│          │
└────┴───────────┴──────────┘       └────────┘                                  └──────────┘
           ▲
           │
           │
┌─────────────────────────────────────────────┐
│                                             │
│               Reference Data                │
│                 Change Sets                 │
│                                             │
└─────────────────────────────────────────────┘
     ▲           ▲           ▲           ▲
     │           │           │           │
     │           │           │           │
┌─────────┐ ┌─────────┐ ┌─────────┐ ┌─────────┐
│         │ │         │ │         │ │         │
│   CSV   │ │  YAML   │ │  JSON   │ │   SQL   │
│         │ │         │ │         │ │         │
└─────────┘ └─────────┘ └─────────┘ └─────────┘
</pre>
<p>In the above scenario the first of the two API calls, <code class="language-plaintext highlighter-rouge">/api/changelog</code> lists the changes sets id and effective dates for the specified projection. The second API call <code class="language-plaintext highlighter-rouge">/api/projection/v1/parks</code> requestes the park data at a specific point in time. The requests are routed via a CDN for caching. When the data behind the projections a hook causes the cache to be invalidated.
However, it’s completely up to you how the projections are accessed - you could build a RESTful API to expose them over HTTP as above, bundle them in a client side JavaScript module or export them as a set of <a href="https://avro.apache.org/">Apache AVRO</a> files to S3.</p>

<h3 id="conclusion">Conclusion</h3>

<p>Filby transforms how you manage shared, temporal reference data, combining the best practices of source control with runtime flexibility, no matter how the data is consumed. It isn’t a turn key system though, you need to model and provide the data, then write the code calls the Filby API to retrieve the reference data at a point in time and expose it to the outside world.</p>

<p>Ready to explore Filby? <a href="https://github.com/acuminous/filby">Start here</a>.</p>]]></content><author><name>Stephen Cresswell</name></author><category term="Temporal" /><category term="Versioned" /><category term="Reference Data" /><category term="PostgreSQL" /><summary type="html"><![CDATA[An open-source library that simplifies managing versioned reference data across distributed systems with consistency, reliability, and flexibility.]]></summary></entry><entry><title type="html">Freedom vs. Frameworks</title><link href="http://www.stephen-cresswell.com/2024/12/25/freedom-vs-frameworks.html" rel="alternate" type="text/html" title="Freedom vs. Frameworks" /><published>2024-12-25T00:00:00+00:00</published><updated>2024-12-25T00:00:00+00:00</updated><id>http://www.stephen-cresswell.com/2024/12/25/freedom-vs-frameworks</id><content type="html" xml:base="http://www.stephen-cresswell.com/2024/12/25/freedom-vs-frameworks.html"><![CDATA[<p>In his book <em>Drive</em>, Dan Pink highlights autonomy as one of the critical motivators for high-performing teams. Autonomy empowers engineers to innovate, solve problems creatively, and own their work. But with great autonomy comes great responsibility — and sometimes, significant challenges. One such challenge is the tendency for engineers to gravitate towards shiny new toys, often prioritising popularity over suitability. I explored this phenomenon in my blog post <a href="https://www.stephen-cresswell.com/2024/04/17/prisma-and-the-naivety-of-crowds.html">“Prisma and the Naivety of Crowds”</a>, where I discussed how crowdsourcing trends can sometimes overshadow thoughtful, context-specific decision-making.</p>

<p>Guidelines are necessary to strike a balance between autonomy and consistency, ensuring that choices align with organisational goals. But guidelines alone are insufficient. As Jeff Bezos famously said, “Good intentions don’t work. Good mechanisms do.” To address this, I’m excited to introduce <a href="https://github.com/acuminous/eslint-plugin-tech-radar">eslint-plugin-tech-radar</a>, a robust mechanism to help engineering teams enforce dependency guidelines at scale.</p>

<h3 id="introducing-eslint-plugin-tech-radar">Introducing eslint-plugin-tech-radar?</h3>

<p>A traditional <a href="https://www.thoughtworks.com/radar/byor">Tech Radar</a> provides a visual framework for evaluating tools and technologies based on maturity and strategic alignment. However, it doesn’t prevent engineers from inadvertently or deliberately installing prohibited modules. Mechanisms like private npm registries or post-installation scans have significant drawbacks—blocking transitive dependencies or acting too late in the pipeline.</p>

<p><strong>eslint-plugin-tech-radar</strong> solves these problems by integrating directly into your development workflow. It provides:</p>

<ul>
  <li><strong>Proactive validation:</strong> Dependencies are checked against your organisation’s Tech Radar during development, pre-commit, or CI/CD stages.</li>
  <li><strong>Shared configuration:</strong> Centralised rules ensure consistent enforcement across repositories.</li>
  <li><strong>Flexibility:</strong> Teams can override or adapt rules on a per-repository basis using familiar ESLint escape hatches.</li>
  <li><strong>Version tracking:</strong> A built-in “latest” rule ensures your shared configuration stays up to date.</li>
</ul>

<p>By leveraging eslint-plugin-tech-radar, teams can adhere to established guidelines without sacrificing agility.</p>

<h3 id="getting-started">Getting Started</h3>

<h4 id="step-1-define-your-tech-radar">Step 1: Define Your Tech Radar</h4>

<p>Start by building your Tech Radar. For example:</p>

<pre><code class="language-csv">name,ring,quadrant,isNew,description
prisma,hold,backend,FALSE,Persistence
winston,hold,backend,FALSE,Logging
bunyan,hold,backend,FALSE,Logging
@pgtyped/query,assess,TRUE,Persistence
orchid-orm,trial,backend,FALSE,Persistence
pino,adopt,backend,FALSE,Logging
sequelize,adopt,backend,FALSE,Persistence
</code></pre>

<p>Export this CSV as a JSON configuration:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>npx <span class="nt">--package</span> eslint-plugin-tech-radar <span class="nt">--</span> export-tech-radar <span class="se">\</span>
  <span class="nt">--input</span> radar.csv <span class="se">\</span>
  <span class="nt">--documentation</span> https://github.com/your-organisation/tech-radar <span class="se">\</span>
  <span class="nt">--output</span> radar.json
</code></pre></div></div>

<h4 id="step-2-create-a-shared-eslint-configuration">Step 2: Create a Shared ESLint Configuration</h4>

<p>Create a shared ESLint configuration that uses your Tech Radar:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"extends"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"eslint:recommended"</span><span class="p">],</span><span class="w">
  </span><span class="nl">"plugins"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"tech-radar"</span><span class="p">],</span><span class="w">
  </span><span class="nl">"rules"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="nl">"tech-radar/adherence"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
      </span><span class="s2">"error"</span><span class="p">,</span><span class="w">
      </span><span class="p">{</span><span class="w">
        </span><span class="nl">"hold"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"prisma"</span><span class="p">,</span><span class="w"> </span><span class="s2">"winston"</span><span class="p">,</span><span class="w"> </span><span class="s2">"bunyan"</span><span class="p">],</span><span class="w">
        </span><span class="nl">"assess"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"@pgtyped/query"</span><span class="p">],</span><span class="w">
        </span><span class="nl">"trial"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"orchid-orm"</span><span class="p">],</span><span class="w">
        </span><span class="nl">"adopt"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"pino"</span><span class="p">,</span><span class="w"> </span><span class="s2">"sequelize"</span><span class="p">],</span><span class="w">
        </span><span class="nl">"ignore"</span><span class="p">:</span><span class="w"> </span><span class="p">[],</span><span class="w">
        </span><span class="nl">"documentation"</span><span class="p">:</span><span class="w"> </span><span class="s2">"https://github.com/your-organisation/tech-radar"</span><span class="w">
      </span><span class="p">}</span><span class="w">
    </span><span class="p">],</span><span class="w">
    </span><span class="nl">"tech-radar/latest"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
      </span><span class="s2">"error"</span><span class="p">,</span><span class="w">
      </span><span class="p">{</span><span class="w">
        </span><span class="nl">"packages"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"eslint-config-your-organisation"</span><span class="p">]</span><span class="w">
      </span><span class="p">}</span><span class="w">
    </span><span class="p">]</span><span class="w">
  </span><span class="p">}</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<h4 id="step-3-enforce-rules-across-repositories">Step 3: Enforce Rules Across Repositories</h4>

<p>Include the shared configuration in your application’s ESLint setup:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"extends"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"eslint-config-your-organisation"</span><span class="p">]</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>Run ESLint as part of your CI/CD pipeline or pre-commit hooks to ensure compliance.</p>

<h3 id="real-world-examples">Real-World Examples</h3>

<p>If your <code class="language-plaintext highlighter-rouge">package.json</code> includes a dependency on <code class="language-plaintext highlighter-rouge">prisma</code> (a “hold” package), ESLint will flag it:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&gt; eslint .

~/your-application/package.json
  1:1  error  Package 'prisma' is discouraged. See https://github.com/your-organisation/tech-radar for more details  tech-radar/adherence

✖ 1 problem (1 error, 0 warnings)
</code></pre></div></div>

<p>If your shared configuration is outdated, the “latest” rule will catch it:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&gt; eslint .

~/your-application/package.json
  1:1  error  Package 'eslint-config-your-organisation' must be version 1.0.2.  tech-radar/latest

✖ 1 problem (1 error, 0 warnings)
</code></pre></div></div>

<h3 id="additional-tips">Additional Tips</h3>

<h4 id="block-installations-using-a-preinstall-script">Block Installations Using a Preinstall Script</h4>

<p>To prevent undesirable dependencies from being installed, run ESLint during <code class="language-plaintext highlighter-rouge">npm install</code>:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"scripts"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="nl">"preinstall"</span><span class="p">:</span><span class="w"> </span><span class="s2">"eslint ."</span><span class="w">
  </span><span class="p">}</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<h4 id="encourage-healthy-discussion">Encourage Healthy Discussion</h4>

<p>Changes to the Tech Radar should be accompanied by documented discussions in pull requests or issues. This fosters transparency and ensures alignment.</p>

<h3 id="conclusion">Conclusion</h3>

<p>Autonomy is essential, but so is alignment. eslint-plugin-tech-radar bridges the gap, providing a scalable mechanism for enforcing dependency guidelines. By embedding this tool in your workflow, you can maintain the freedom engineers need to innovate while ensuring their choices align with organisational objectives.</p>

<p>Ready to give it a try? Check out the <a href="https://github.com/acuminous/eslint-plugin-tech-radar">GitHub repository</a> for more details and start building a better, more consistent codebase today.</p>

<hr />
<p><br /></p>

<h4 id="recommended-reading">Recommended Reading</h4>
<ul>
  <li><a href="https://www.danpink.com/books/drive/">Drive</a></li>
</ul>]]></content><author><name>Stephen Cresswell</name></author><category term="Autonomy" /><category term="Control" /><category term="Engineering" /><category term="Leadership" /><category term="Management" /><category term="Tech Radar" /><summary type="html"><![CDATA[Balancing engineering autonomy with organisational standards through eslint-plugin-tech-radar - a mechanism that enforces dependency guidelines without sacrificing developer freedom.]]></summary></entry><entry><title type="html">Turn The Team Around!</title><link href="http://www.stephen-cresswell.com/2024/12/24/turn-the-team-around.html" rel="alternate" type="text/html" title="Turn The Team Around!" /><published>2024-12-24T00:00:00+00:00</published><updated>2024-12-24T00:00:00+00:00</updated><id>http://www.stephen-cresswell.com/2024/12/24/turn-the-team-around</id><content type="html" xml:base="http://www.stephen-cresswell.com/2024/12/24/turn-the-team-around.html"><![CDATA[<p>Targets can be a double-edged sword. When poorly conceived they encourage behaviours that prioritise metrics over real success. For instance, setting a goal like “close 100 tickets this quarter” might push a team to focus on easy wins rather than meaningful work. However, I once encountered a target that broke this mould and completely shifted my perspective. It was when challenged to “make Portal a destination team”.</p>

<p>At the time, the School Portal team had a poor reputation. Engineers were reluctant to join, citing a disjointed codebase and a team culture that, while professional, felt siloed and under immense pressure. David’s target wasn’t about deliverables; it was about creating a team environment where people wanted to be. Success would be measured by whether engineers were eager to join us.</p>

<h3 id="taking-stock">Taking Stock</h3>

<p>When I first joined the Portal team, I took a close look at the challenges we faced. The problems were easy to spot but significant in scale. The four engineers on the team were working in isolation, each handling months-long initiatives. This approach had been the norm for over a year, leading to knowledge silos. There was no slack. If something broke, only the original developer could fix it, and this would derail whatever feature they were currently working on. The product manager was constantly juggling stakeholder expectations amidst these disruptions, and rapidly losing their confidence.</p>

<p>The quality of the work also left much to be desired. Without collaboration or shared accountability, individual coding styles went unchecked. For example, I know my tendency to overcomplicate solutions needs balancing input from others, but here, such feedback loops were nonexistent. The user experience was no better. Customers frequently reported “bugs” that were actually just confusing designs that violated basic UX principles.</p>

<p>An earlier attempt to fix the codebase had backfired. The team had embarked on a large-scale refactor, but without breaking it into manageable, independent deliverables. They didn’t finish a quarter of the work before their three-month grace period elapsed, leaving the code in an even worse state than before. This was compounded by architectural issues which resulted in frequent timeouts and race conditions.</p>

<p>The planning board was another headache. Hundreds of tickets sat there — bugs, technical improvements, features. It was impossible to prioritise effectively. Meanwhile, bugs were piling up, creating a flood of failure demand (work caused by defects or inefficiencies, as opposed to value demand which directly serves customer needs). One bug in particular highlighted the problem. Over the course of a year, an issue with embedded videos was reported five times by different customers. Each time, it was investigated, deemed low priority, and closed without being fixed. This resulted in a poor customer experience and wasted time not only for our team but also for the company’s helpdesk. Each report required a day of investigation, yet fixing the issue outright would have taken less than two day.</p>

<p>What struck me most, though, was the team’s attitude. They openly disparaged the codebase. It reminded me of a story from “Turn the Ship Around!” by L. David Marquet, where the submarine crew were ashamed of their vessel until they rediscovered pride in their work. The Portal team needed that same shift in mindset.</p>

<h3 id="turning-the-tide">Turning the Tide</h3>

<p>The first challenge was morale. Without hope for change, there would be no progress. Luckily, I had an ace up my sleeve: John Hustler, a colleague and friend. John’s thoughtful approach and willingness to go where he was needed most made him the perfect addition. When he joined, it gave me the support I needed to align the team.</p>

<p>To foster a sense of pride, I introduced a small but symbolic initiative. We created a “Show Portal Some Love” ticket. Every time someone made an improvement, no matter how small, they earned a ❤️. The team may have thought it a bit childish, but my hope was that it gave them permission to make things better, while celebrating small wins and lightening the mood. Slowly but surely, they started to see the Portal as something worth investing in.</p>

<p>The next step was tackling waste. I reviewed every ticket on our bloated planning board, moving low-priority ones to a separate board and closing those that weren’t worth pursuing. The issues I moved weren’t high-priority from the product perspective, but they generated a lot of noise or failure demand. I broke them down into clear, actionable steps and with the help of a borrowed contractor, chipped away at them. Quick wins, like simple UX improvements reduced customer confusion and lowered the volume of reported issues. We also removed unreliable, nice-to-have features, such as a tool for exporting CVs as a single PDF. This feature failed one in ten times, often crashing the system or timing out. Fixing it would have taken weeks, but removing it took minutes, eliminating a major source of frustration for both users and the team.</p>

<p>With fewer interruptions, the team could finally focus. The improved flow created a virtuous cycle: more capacity led to more fixes and a higher standard of work, which led to even greater capacity. Over time, we gained enough breathing room to address deeper issues, like architectural flaws.</p>

<p>Meanwhile, I worked with the product manager and Chief Product Officer to reduce the team’s workload. We dropped one of the large deliverables, freeing up an engineer to focus on improvements. This decision, though difficult, paid off as the team regained momentum.</p>

<h3 id="a-new-way-of-working">A New Way of Working</h3>

<p>Once the immediate crises were under control, I shifted our approach. Instead of each engineer tackling separate features, we began working together on a single epic. Our first shared effort was integrating social media into the Portal jobs platform. The team was initially skeptical. They worried it would slow them down, but the results spoke for themselves.</p>

<p>Working together meant we could deliver incrementally. Instead of waiting three months to finish three separate features, we completed one feature in the first month, another in the second, and the final one in the third. Not only did this approach deliver value faster, but it also fostered collaboration and shared ownership.</p>

<h3 id="the-results">The Results</h3>

<p>Within six months, the transformation was evident. The backlog was cleared, the main board had fewer than 25 tickets, and morale was at an all-time high. Six months later, the team had re-architected the application, eliminating performance bottlenecks and race conditions while continuing to deliver product features. We showcased our work at departmental demos, and, for the first time, other engineers were expressing interest in joining the Portal team.</p>

<p>By focusing on collaboration, reducing waste, and building pride, we had turned the team around. The journey wasn’t about individual heroics but about creating an environment where the team could thrive. It’s proof that with the right focus, any team can become a destination team.</p>

<hr />
<p><br /></p>
<h4 id="recommended-reading">Recommended Reading</h4>
<ul>
  <li><a href="https://davidmarquet.com/turn-the-ship-around-book/">Turn the Ship Around!</a></li>
  <li><a href="https://www.nngroup.com/books/design-everyday-things-revised/">The Design of Everyday Things</a></li>
</ul>]]></content><author><name>Stephen Cresswell</name></author><category term="Team" /><category term="Rescue" /><category term="Motivation" /><category term="Slack" /><category term="Waste" /><category term="Agile" /><category term="Targets" /><summary type="html"><![CDATA[How a single unconventional target - 'make Portal a destination team' - transformed a struggling, siloed team into one where engineers wanted to work.]]></summary></entry></feed>